Tech talk · Token Meter

Optimizing Value with Token Meter

Pratik BhavsarAI Engineer @ Cisco · ex-Galileo
Runs onmacOS menu barLinux trayWindows beta · notification area
AgentsClaude Code & DesktopCodexCursorOpenCodeKiroPi

Who's talking

Full-stack AI, then three years deep in evals

Search · NLP · model buildingEvals · tokenomics
2017–2020
TaskHuman · Morningstar
Search, recsys, quant ML
2020
Jina AI
Neural search, employee #6
2021–2023
Enterpret
Founding engineer, NLP
2023–2026
Galileo
Evals, benchmarks, 5 books
2026–now
Cisco
Agent tokenomics, evals
Built
  • BRAG · four open RAG models
  • NLP and search in production
  • Token Meter · agent spend, locally
Evaluated
  • Agent Leaderboard v2 · 30+ models
  • Hallucination Index · RAG
  • Eval Engineering + 4 more books
pratik.ai pakodas.substack.com IIT Bombay · The Batch · Latent Space

The problem · usage is not value

The chat says "Done." The bill says more.

What you see
Fix the failing dashboard tests and open a PR.
· · · 143 minutes later · · ·
Done. Tests pass and the PR is open. ✓
What actually happened · Sessions → Execution profile
Execution profileTokensCostContextToolsWait% of 258K window
context70% watch85% highcompaction
452model calls, each re-reading the whole context
59.7Mtokens read and written
5compactions · first at 95% of the window
143minutes of active work
126skills loaded · 7 used
$26.97the bill, at list price

One real Codex session (gpt-5.6-sol) from my laptop, August 2026. Chat text illustrative; the numbers are real.

How it works

A glance now. A deep dive later.
CodeFileEdit>$67.77 · 28 tok/s · 257K ctx · $9.64 today⌁Wed 2:14 PM
127.0.0.1:8722 · Spend
Token Meter dashboard Spend page
TM
Token Meternow
Long sessionClaude Code · claude-opus-5-5
1 2 3 4 5
  1. 1
    Live titleCost, speed, context, and today's spend. Pick the metrics.
  2. 2
    One click to the dashboardThe deep dive at 127.0.0.1:8722: every session, every month
  3. 3
    Follow latest, or pin oneAny recent session, any agent
  4. 4
    Budgets, goals, limitsSubmenus, without opening a browser
  5. 5
    Nudges as notificationsApp and model only, never content
macOSMenu bar LinuxAppIndicator tray WindowsNotification area Beta
AgentsClaude Code & DesktopCodexCursorOpenCodeKiroPi

The macOS menu bar companion. Linux and Windows show the same data in the tray. Menu values illustrative.

How it works

From raw traces to goals

No API keys, no proxy, no extra logging. If the agent wrote it to disk, Token Meter can read it, including months of history.

Part 2 · Act 1 of 4

What am I spending?

This session, and this month. Sessions · Spend

01–02What am I spending?
03–05Where does it go?
06–07How is it going?
08–10Can I do better?

What am I spending? · 1 of 10

"What did this session just cost me?"

  1. 1
    Spend todayAll agents, so far today
  2. 2
    Live cost per sessionUpdates as the agent works
  3. 3
    Context in useHow full the window is getting
  4. 4
    Menu barLive cost, speed, context, and today's spend, plus nudges as notifications
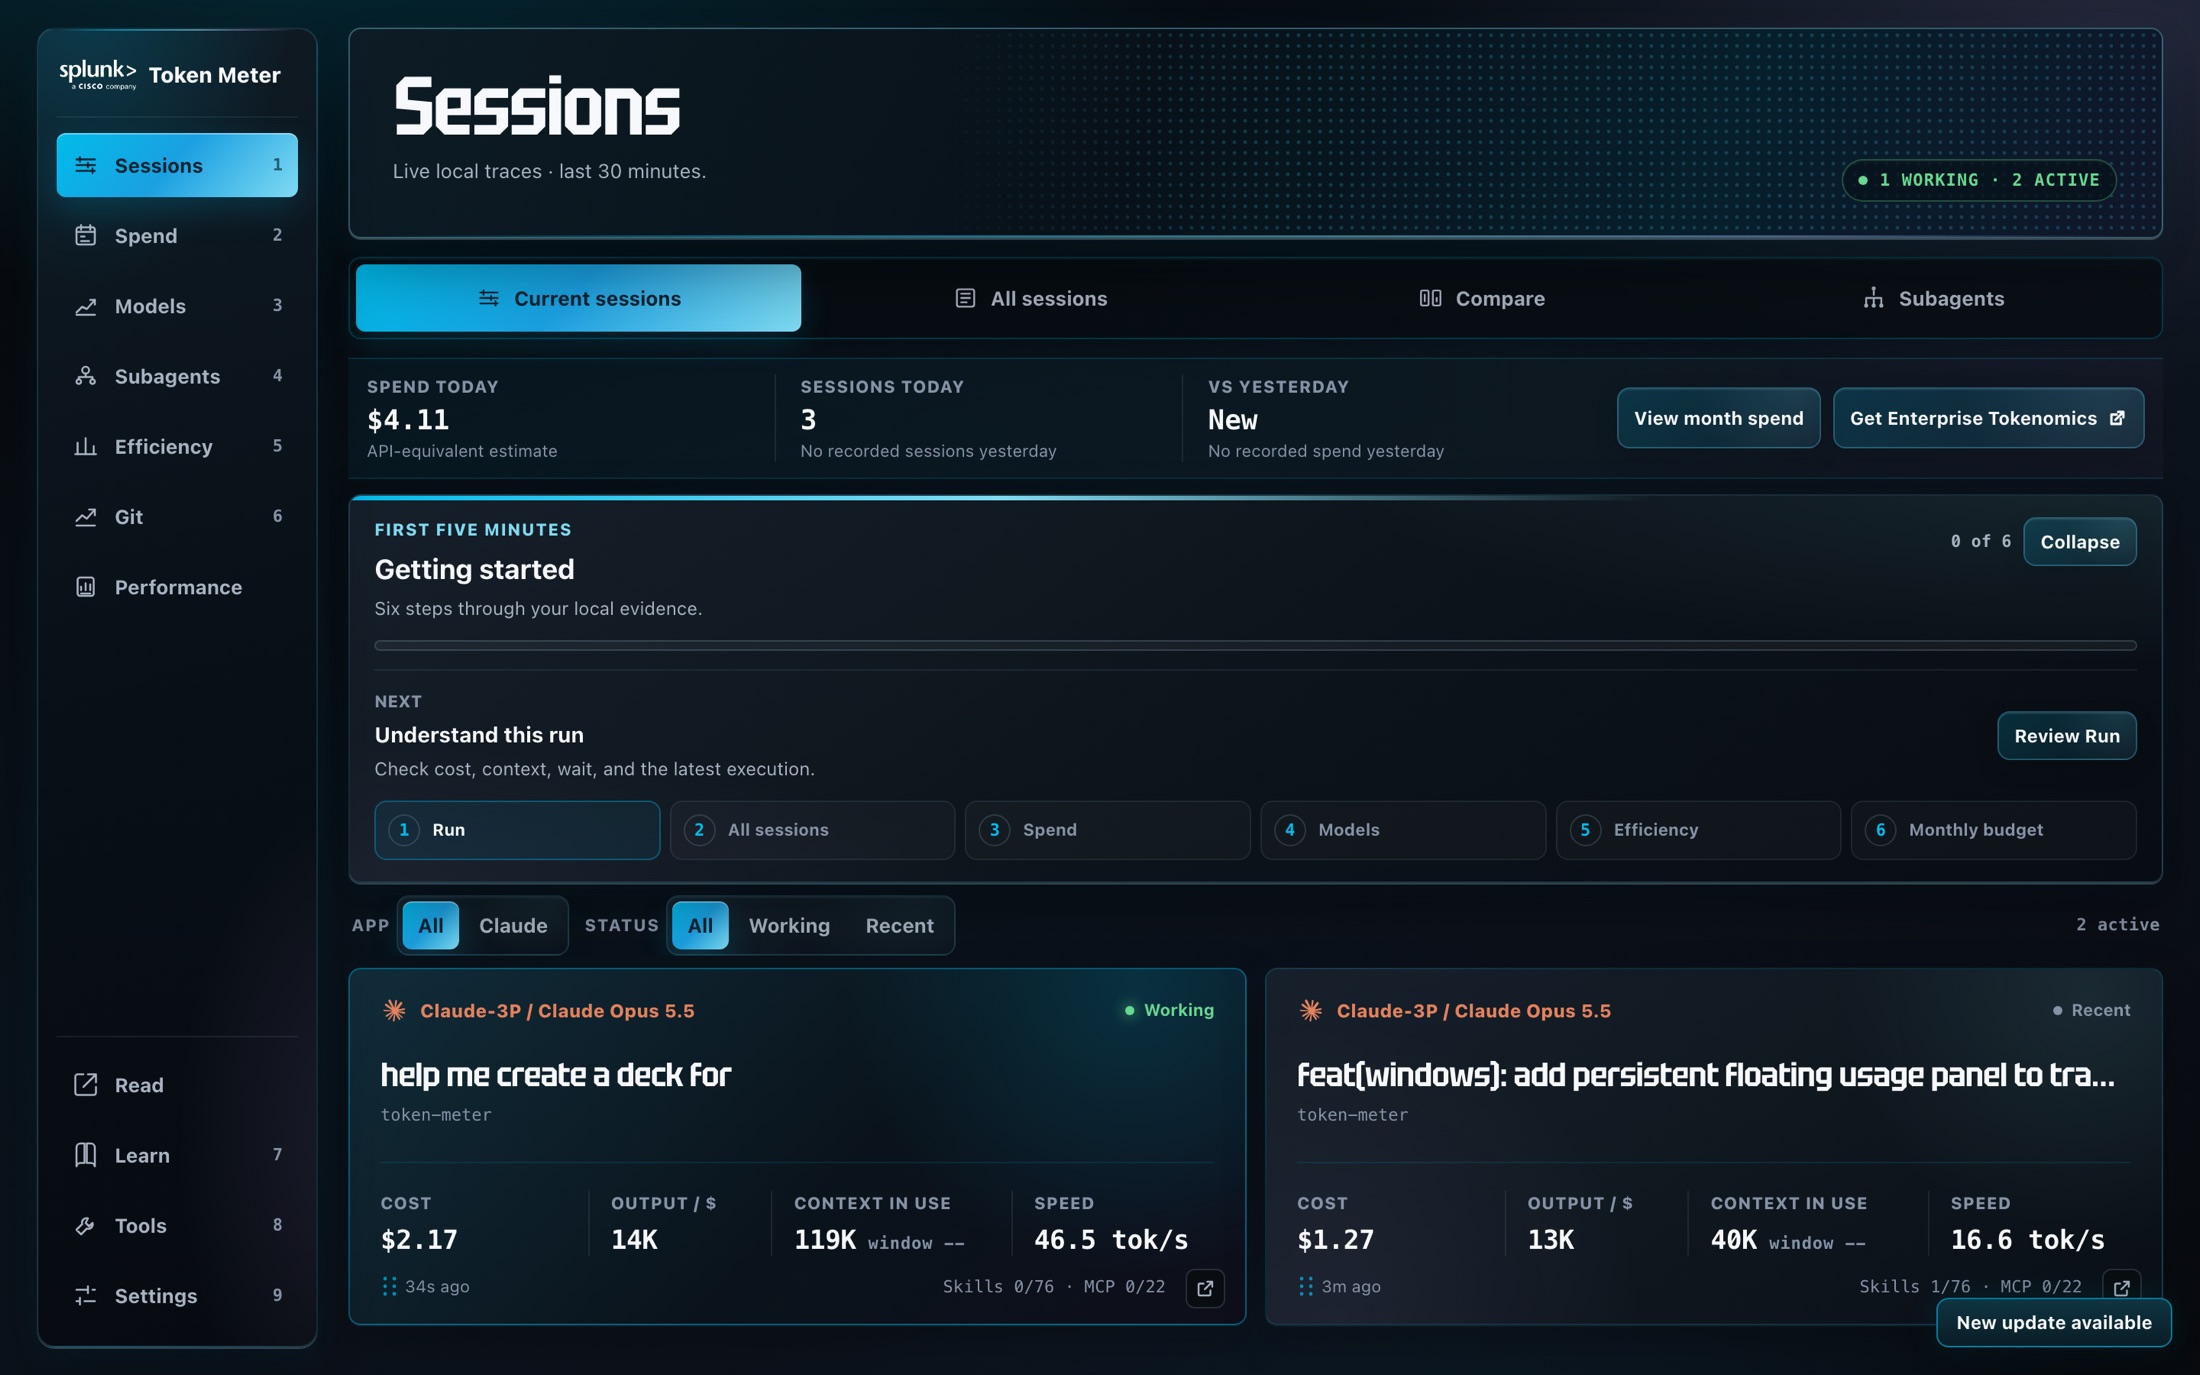
When context climbs, compact or start a fresh session.
Current sessions with live cost, output per dollar, context, and speed
>$67.77 · 28 tok/s · 257K ctx · $9.64 today⌁Wed 2:14 PM
TM
Token Meternow
Long sessionClaude Code · claude-opus-5-5

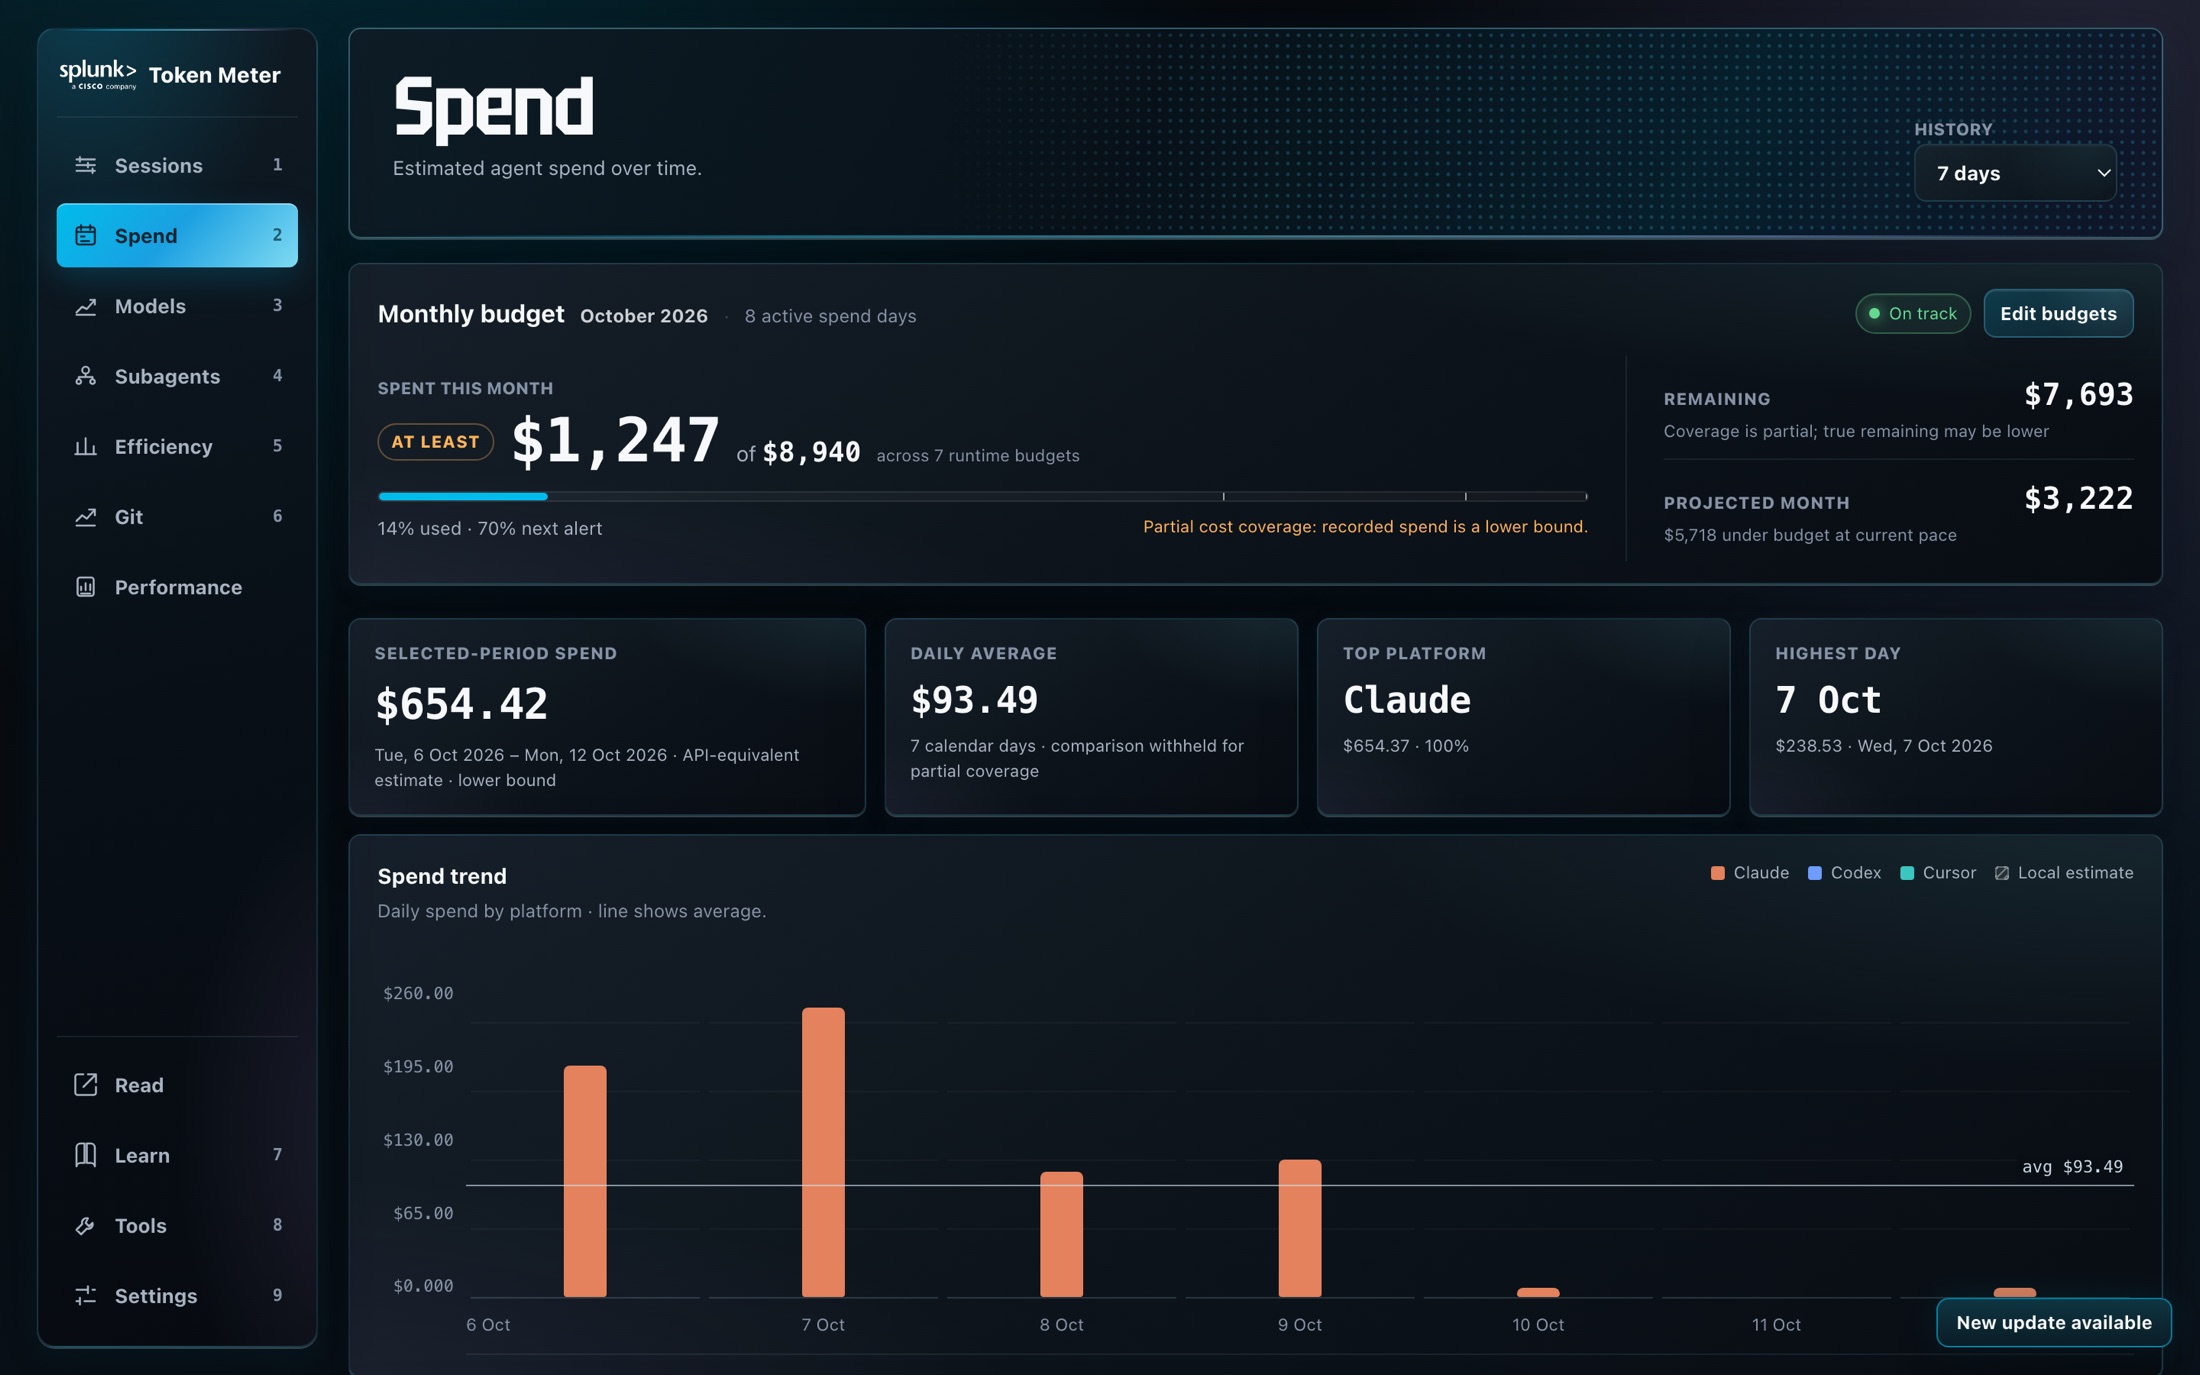
What am I spending? · 2 of 10

"Am I on track this month?"

  1. 1
    Spent this month$1,247 in 12 days. "At least" because some sessions lack cost data.
  2. 2
    Projected month$3,222 at the current pace. On track.
JunJulAugSepOct $2.1K$1.2K
Spend page with monthly budget, projected month, and daily spend trend
Projected month
$3,222
$5,718 under budget at this pace

My laptop, estimated at public list prices. October is month-to-date.

Part 2 · Act 2 of 4

Where does it go?

Which model, which agents, and which tools. Models · Subagents · Tools

01–02What am I spending?
03–05Where does it go?
06–07How is it going?
08–10Can I do better?

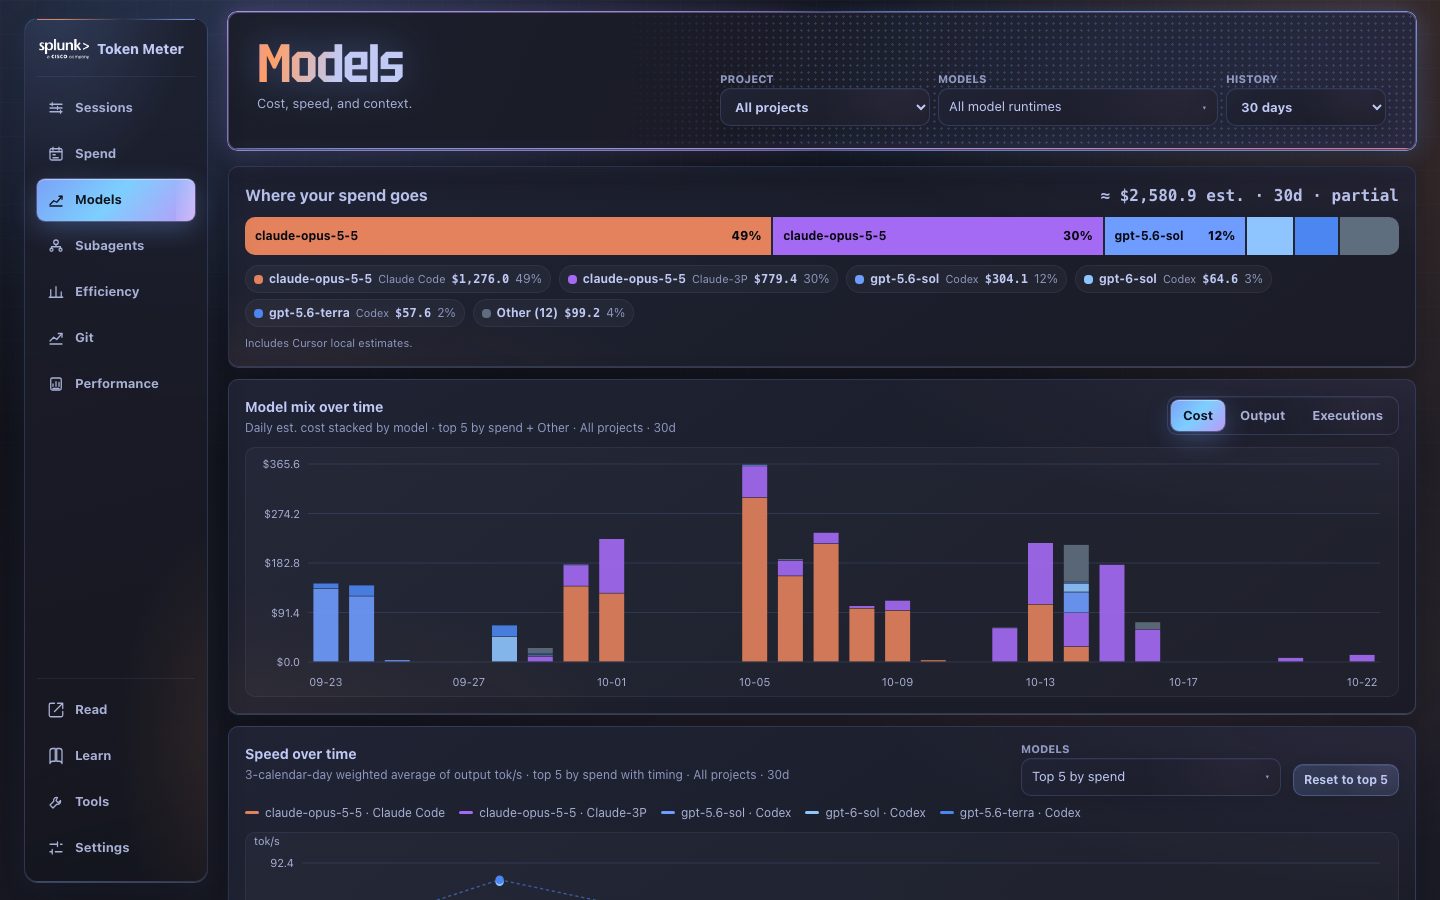
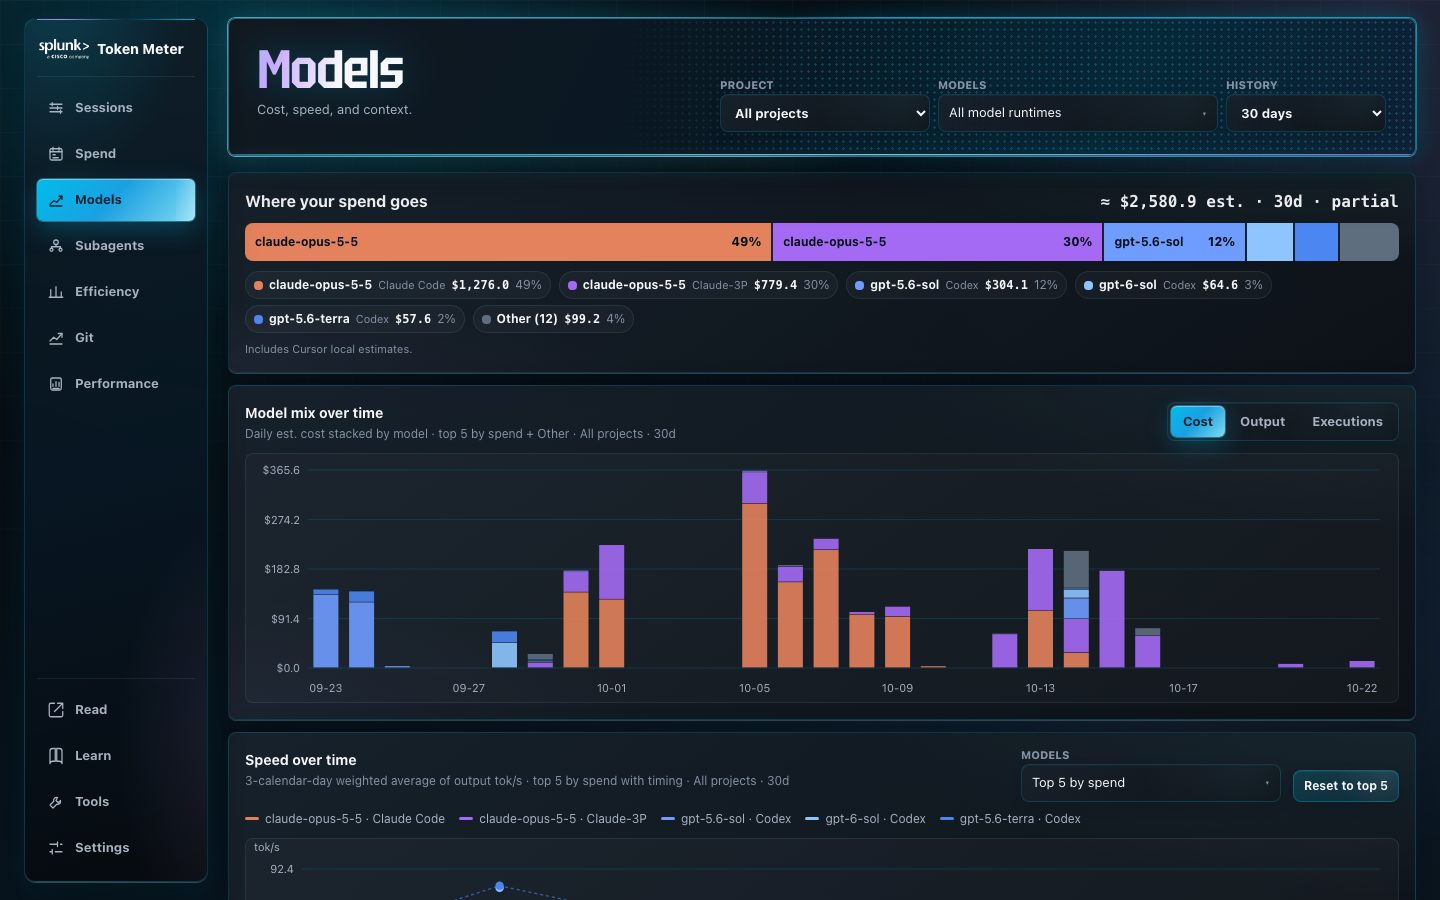
Where does it go? · 3 of 10

"Is my model slower, or just pricier?"

  1. 1
    Where the spend goesOne model took 56% of my last 30 days
  2. 2
    Model mix over timeThe day I switched from Codex to Claude is visible
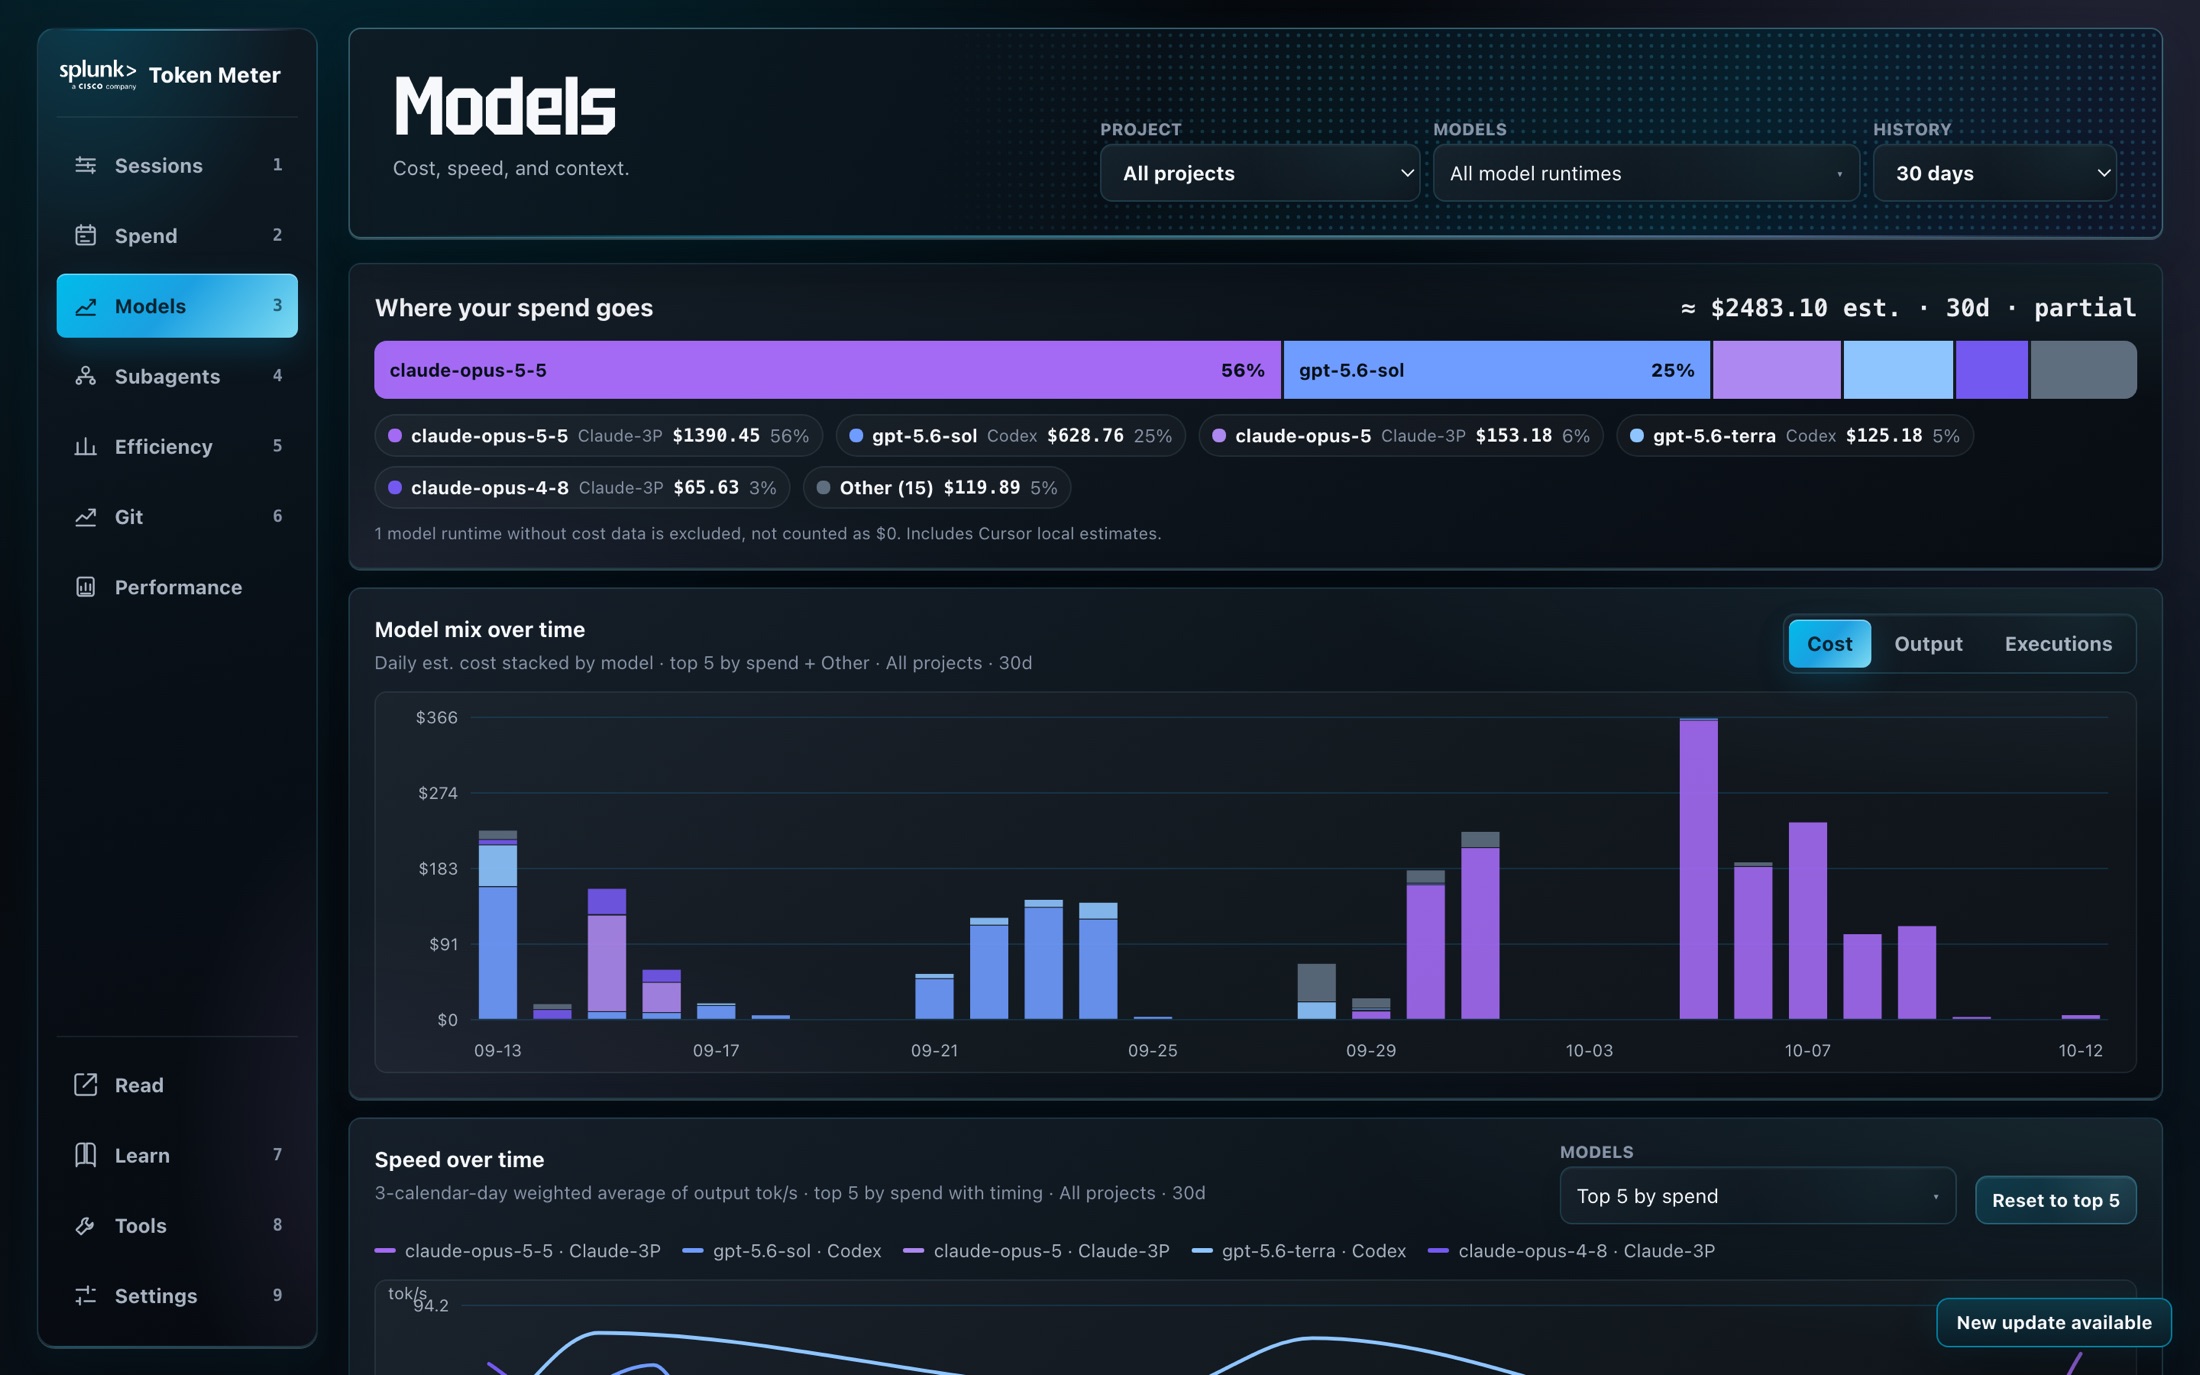
Check speed over time per model. Same name in different apps is a different history.
Models page with spend by model, model mix over time, and speed over time
Where the spend goes
56%
claude-opus-5-5 · $1,390 in 30 days

Where does it go? · 4 of 10

Do cheaper subagents make me faster and cheaper?
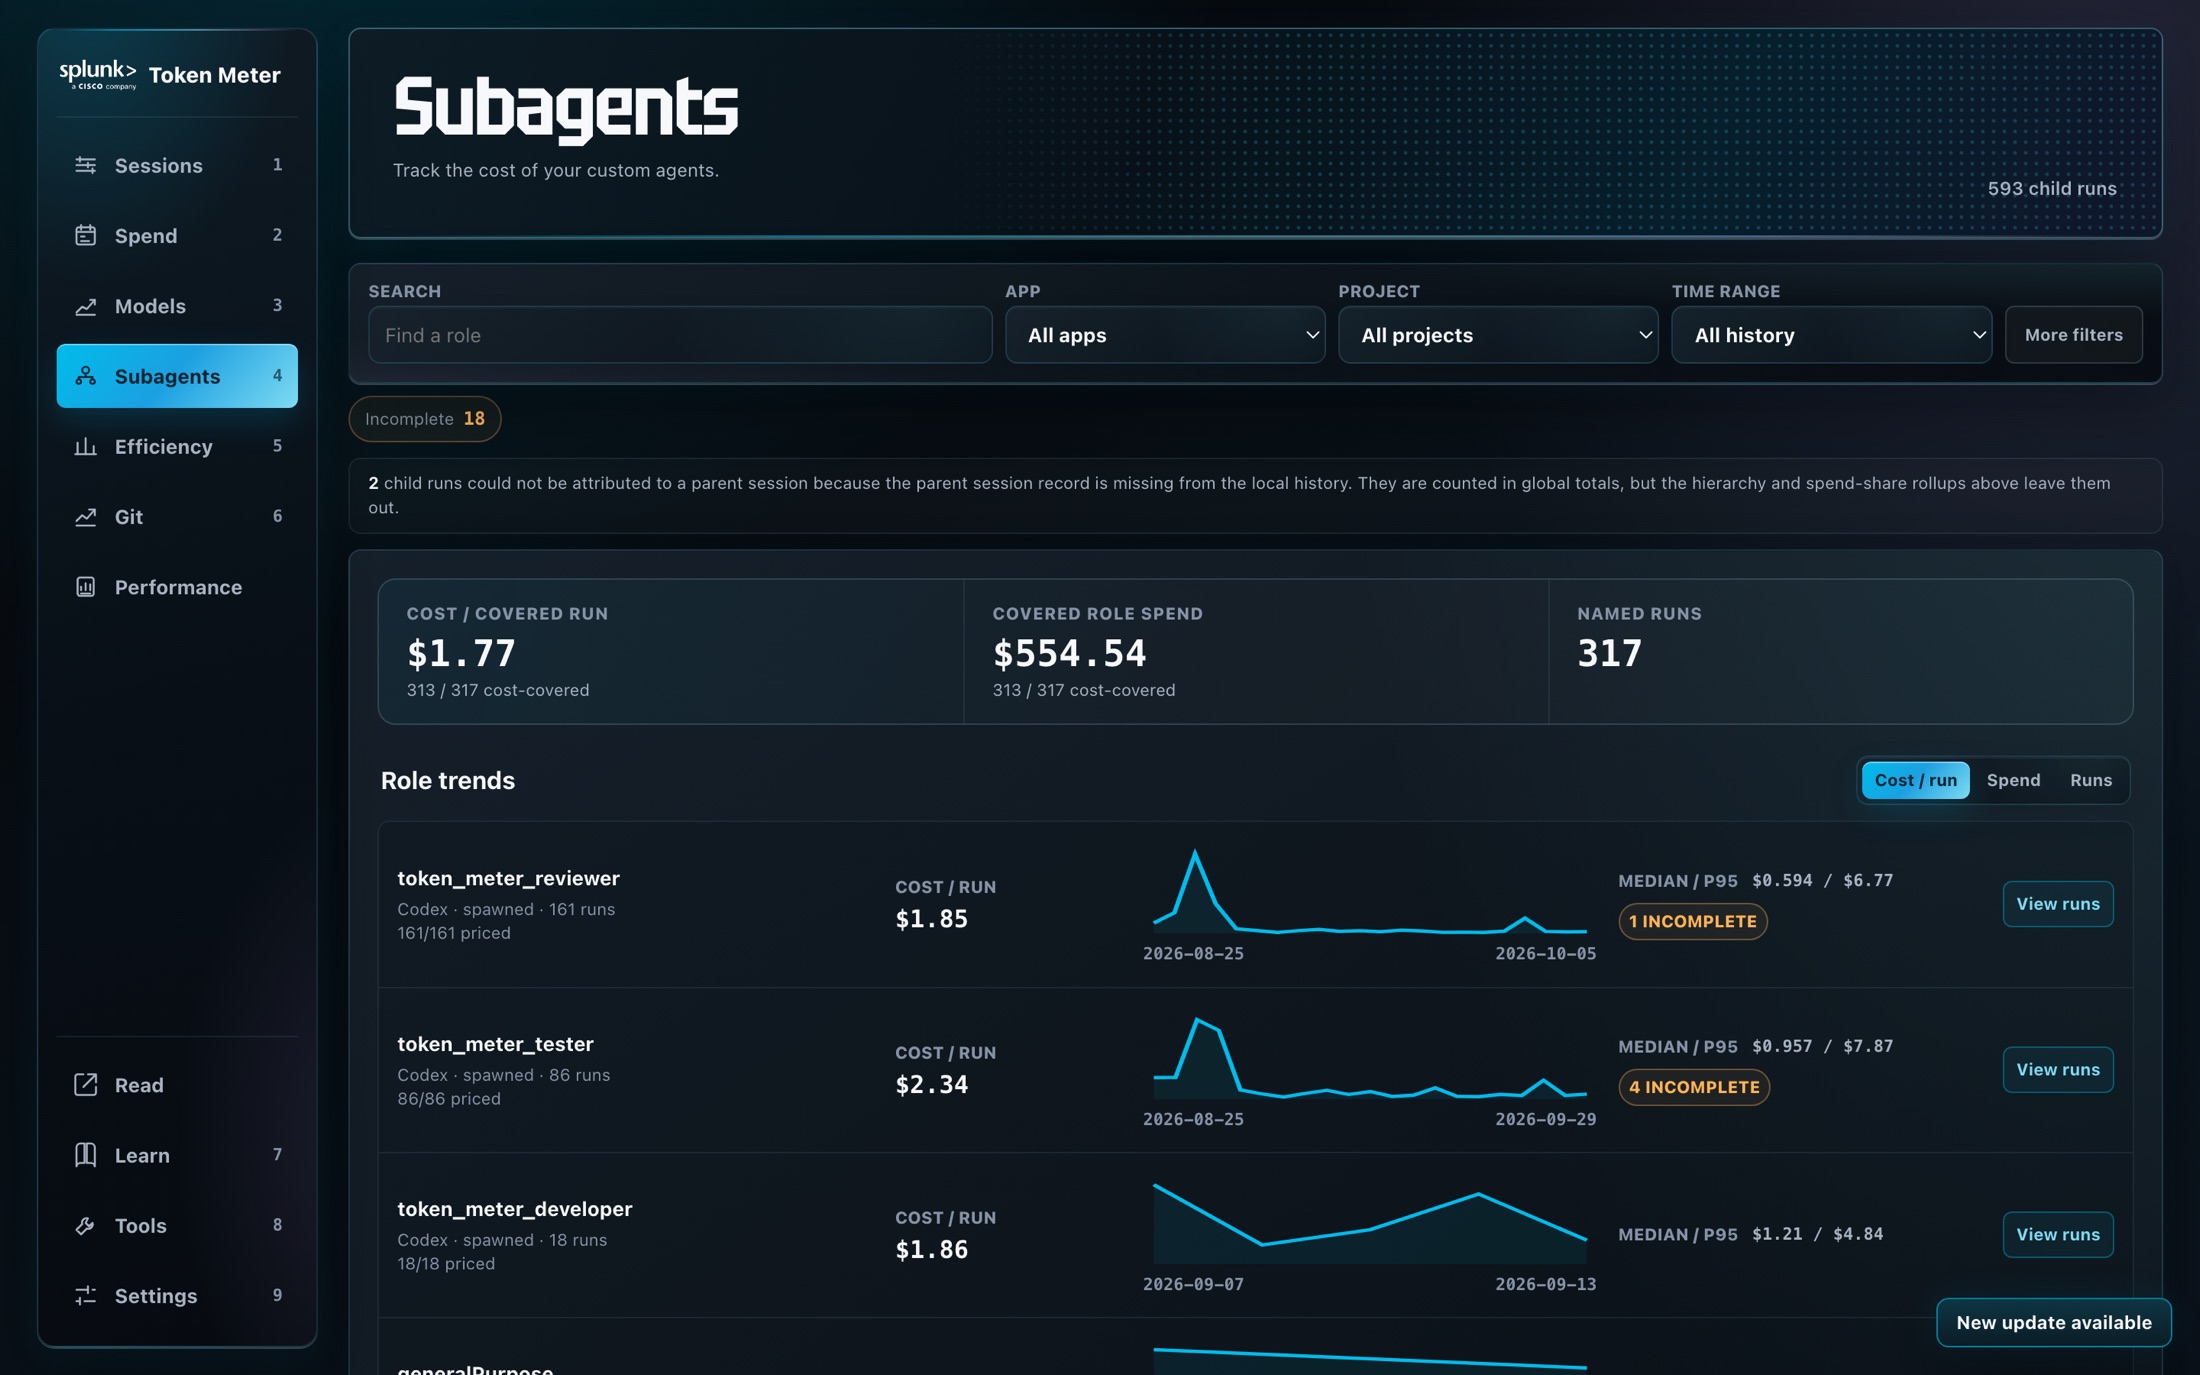
Cost per run
$0.923.9× less
terra vs. $3.54 on sol
Median run time
262s28% faster
vs. 365s on sol
Output per $
10.2K1.8×
vs. 5.8K overall
Share of spend
34%
of subagent sessions
Send review, test, and explore to cheaper models.
Subagents page with cost per run and role trends

My laptop · 702 child runs · run times compare different task mixes, so read them as directional.

Where does it go? · 5 of 10

"Which tools and skills are dead weight?"
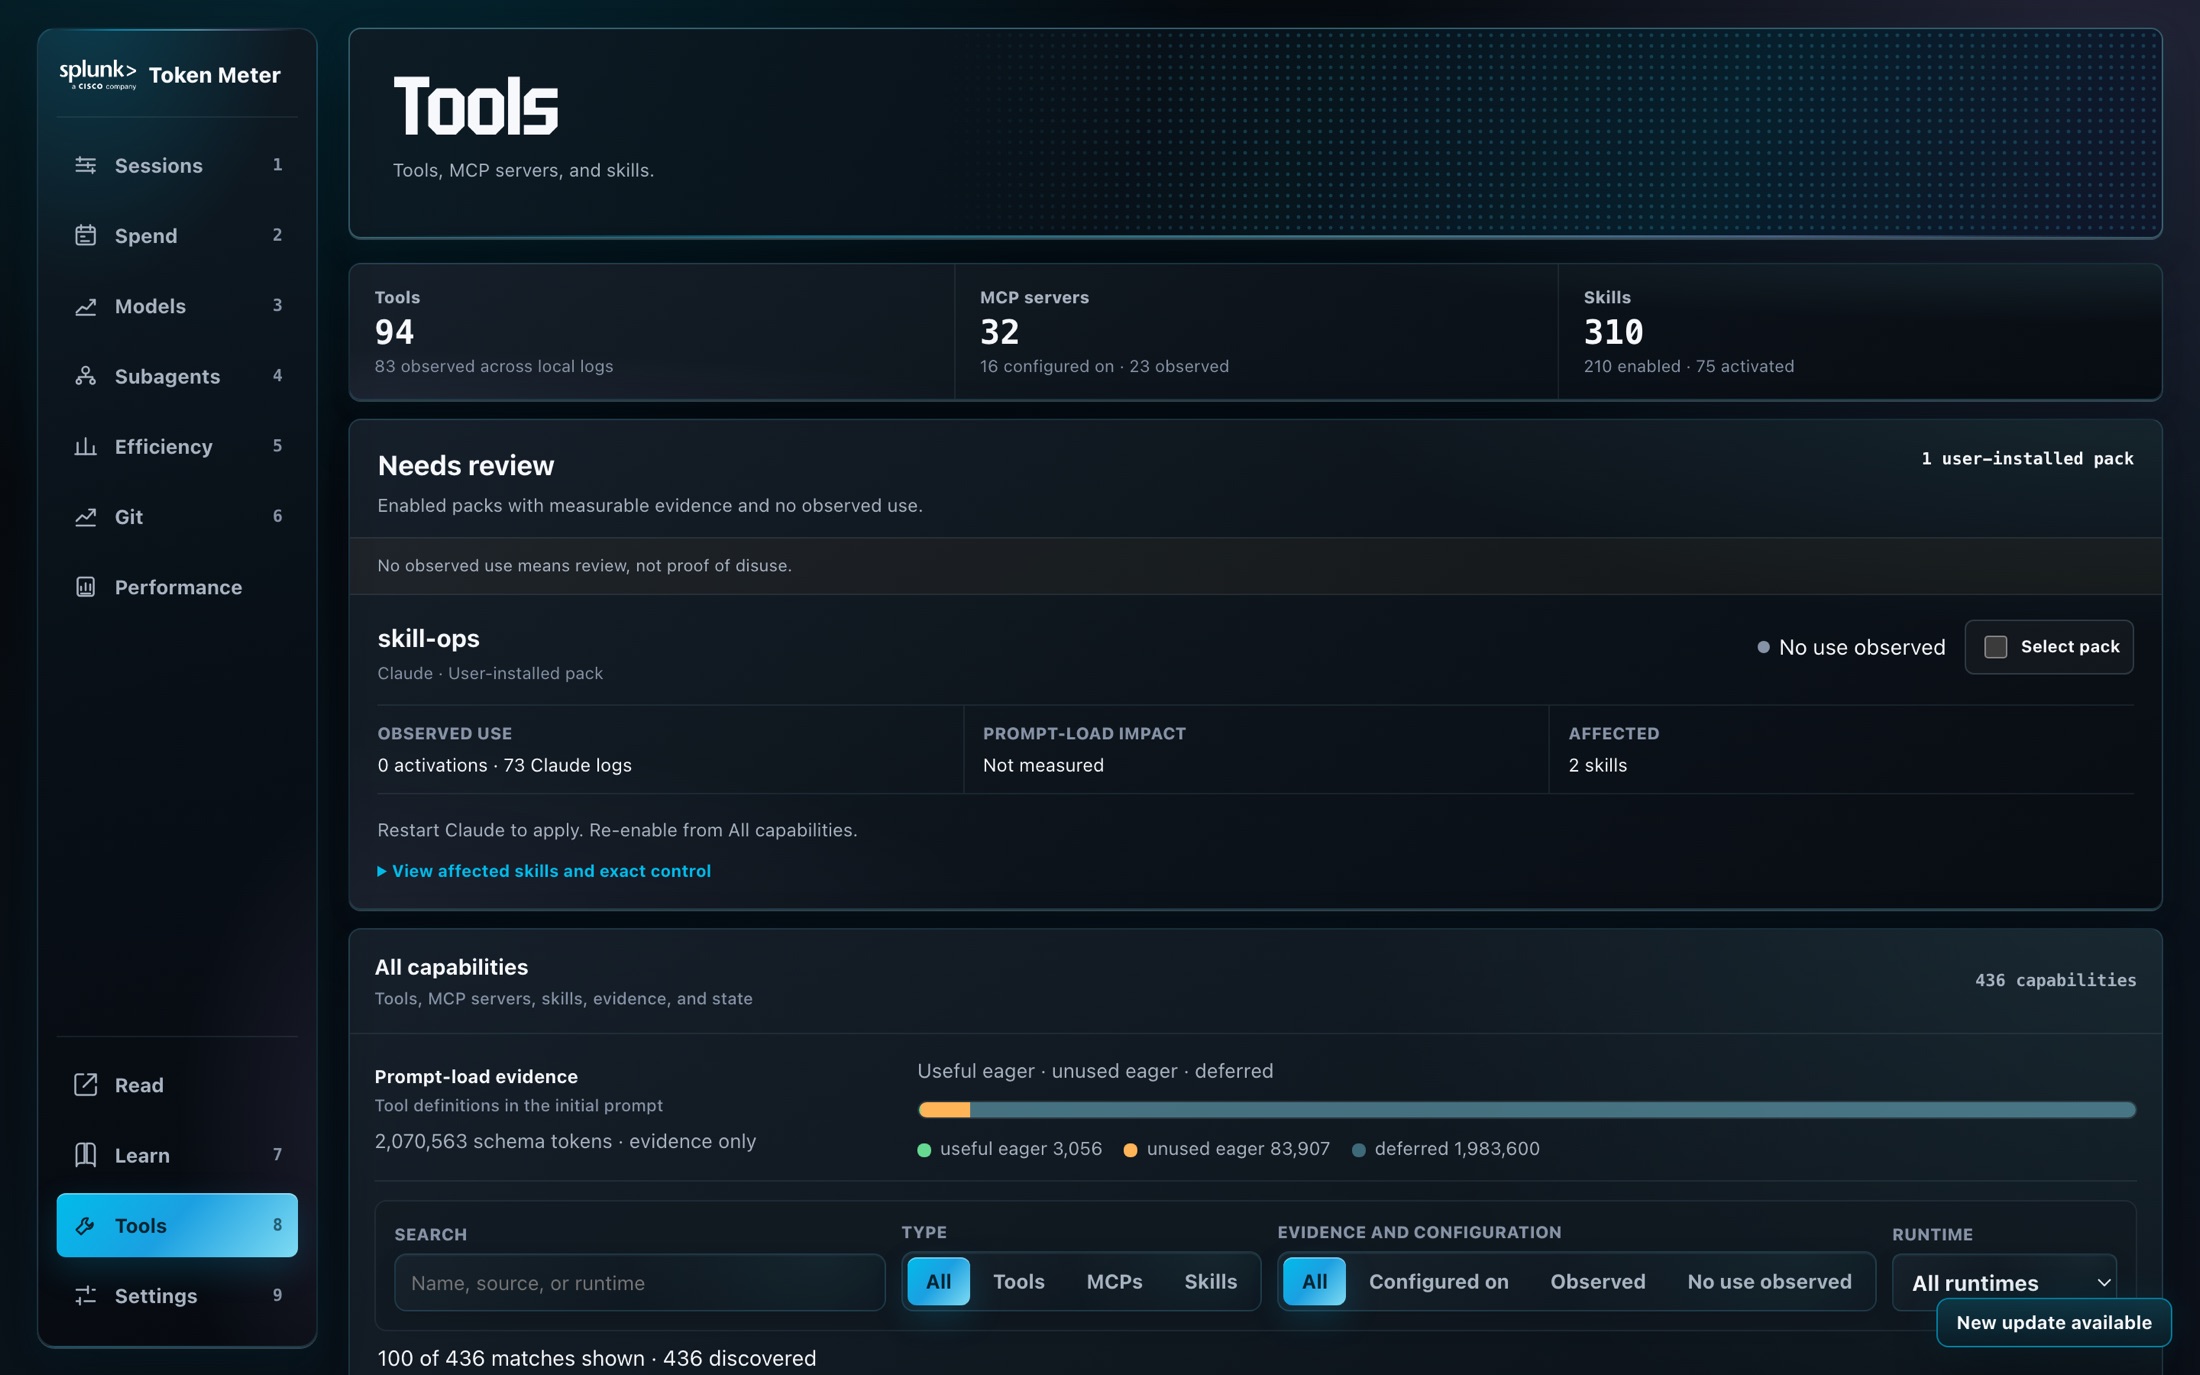
1Unused definitions
83.9K96% unused
schema tokens never called
2Skills that ran
75of 217
enabled skills ever used
MCP servers used
8of 16
enabled servers ever called
Tool output
148Mtokens
returned · 78% from Codex exec
Turn off unused packs. Ask tools for narrower output.
Tools page with capability counts, unused packs, and prompt-load evidence

Part 2 · Act 3 of 4

How is it going?

Whether I'm getting more efficient, and what the spend shipped. Efficiency · Git

01–02What am I spending?
03–05Where does it go?
06–07How is it going?
08–10Can I do better?

How is it going? · 6 of 10

"Am I getting more efficient?"

  1. Output per $ · 4.4KDown 30% on the week before
  2. Context load · 377×Input per output token, up 24%
  3. By modelSame model, 4.5× the value: 19K output per $ in short sessions, 4.2K in one long one
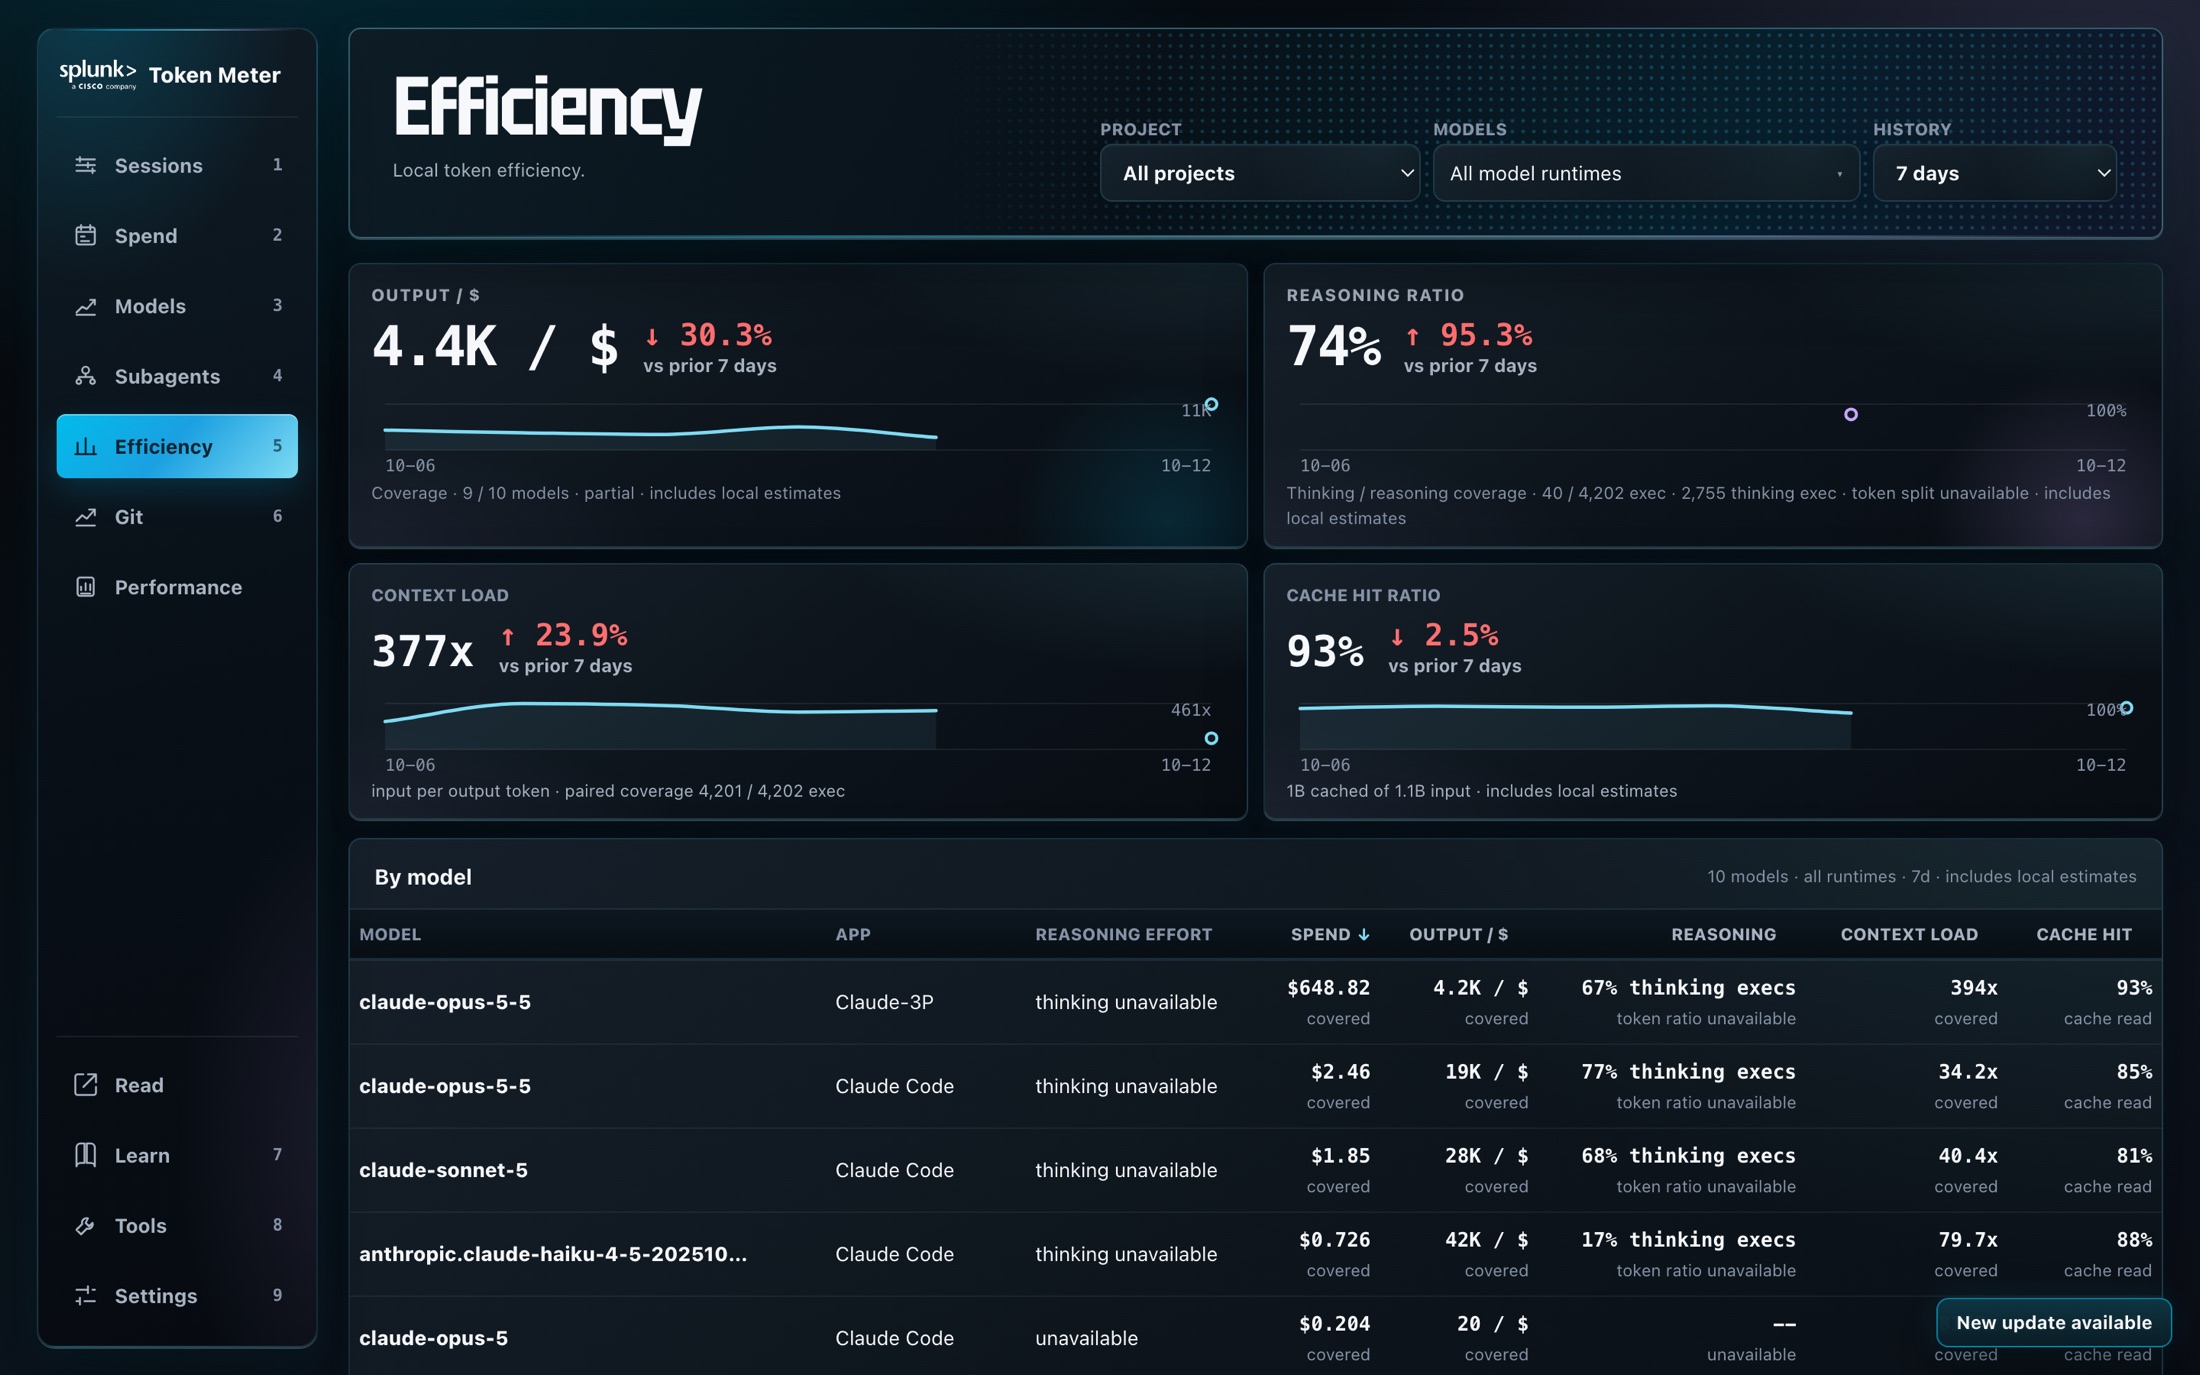
When context load climbs, compact or start fresh.
Efficiency page with output per dollar, reasoning ratio, context load, and cache hit ratio

My laptop · last 7 days vs. the 7 before · by-model rows from the Efficiency table.

How is it going? · 7 of 10

"What did I ship per dollar?"

  1. 1
    Spend per 1K pushed lines$31.72 this week, up 18%
  2. 2
    Push yieldPushed lines per 1K output tokens
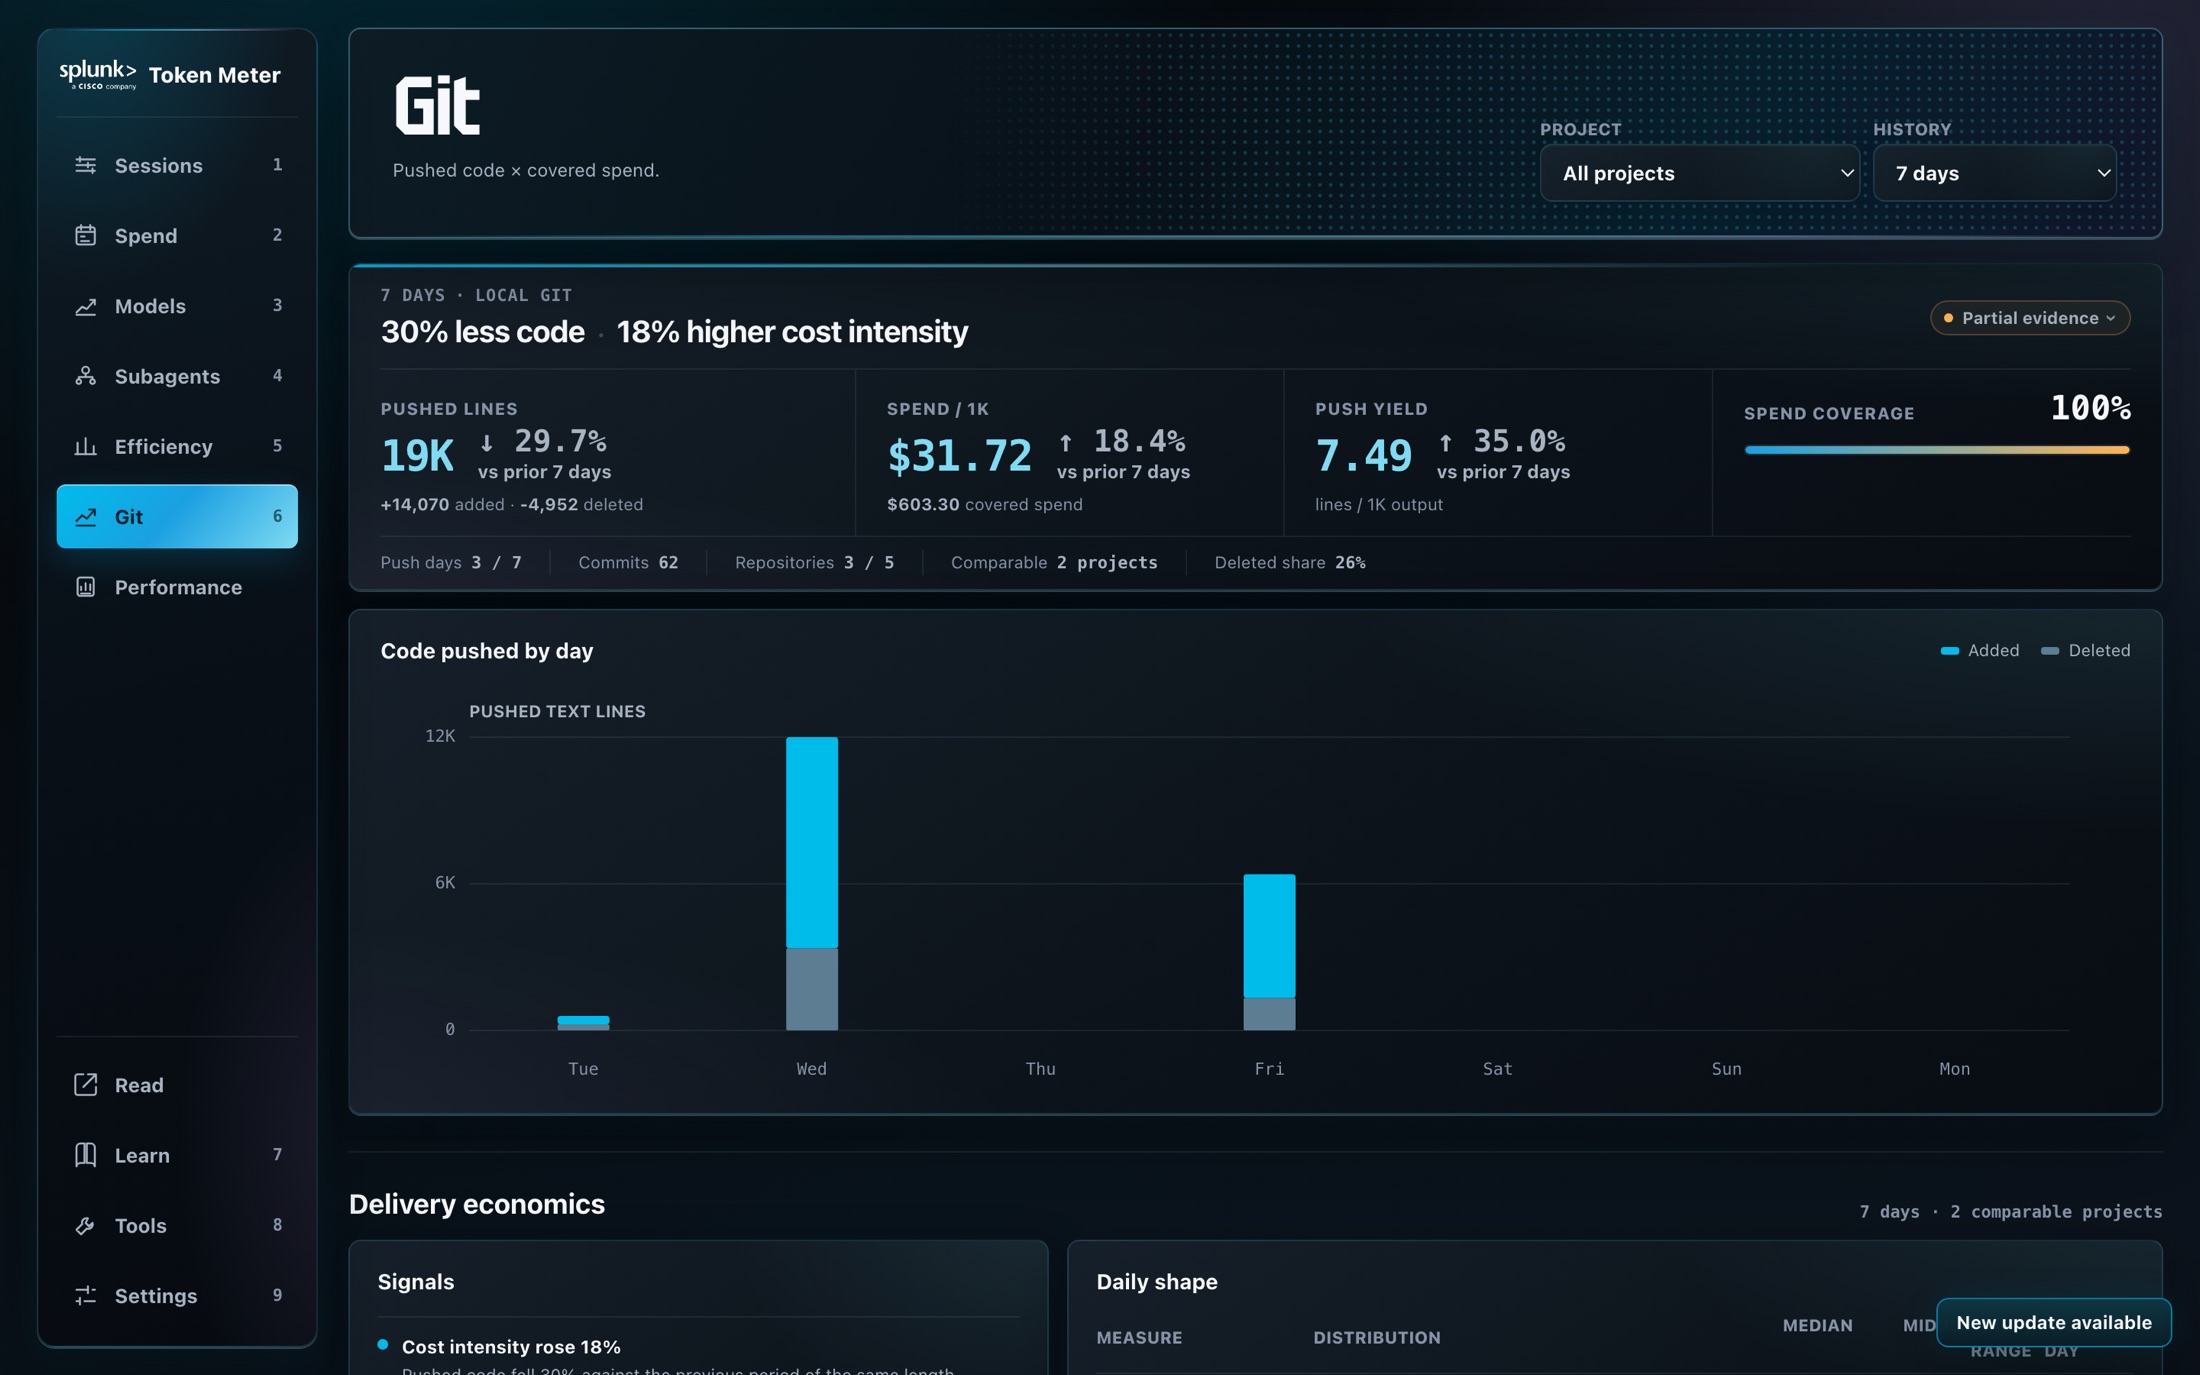
Read it as a mechanical signal, not a productivity score. Faster coding doesn't ship faster if review or release is the next bottleneck.
Git page with pushed lines, spend per 1K lines, push yield, and daily code changes
Spend per 1K pushed lines
$31.72↑ 18.4%
vs. the prior 7 days

Part 2 · Act 4 of 4

Can I do better?

Right-sizing, live nudges, and goals. Work and nudges (coming soon) · Goals

01–02What am I spending?
03–05Where does it go?
06–07How is it going?
08–10Can I do better?

Can I do better? · 8 of 10 Coming soon

"Where did my money actually go?"

  1. 1
    Model suggestions$1,836 possible saving by moving routine work to a cheaper model
  2. 2
    Reasoning suggestions153 routine requests ran at xhigh effort
  3. 3
    Pushback15% of 1,964 follow-ups pushed back
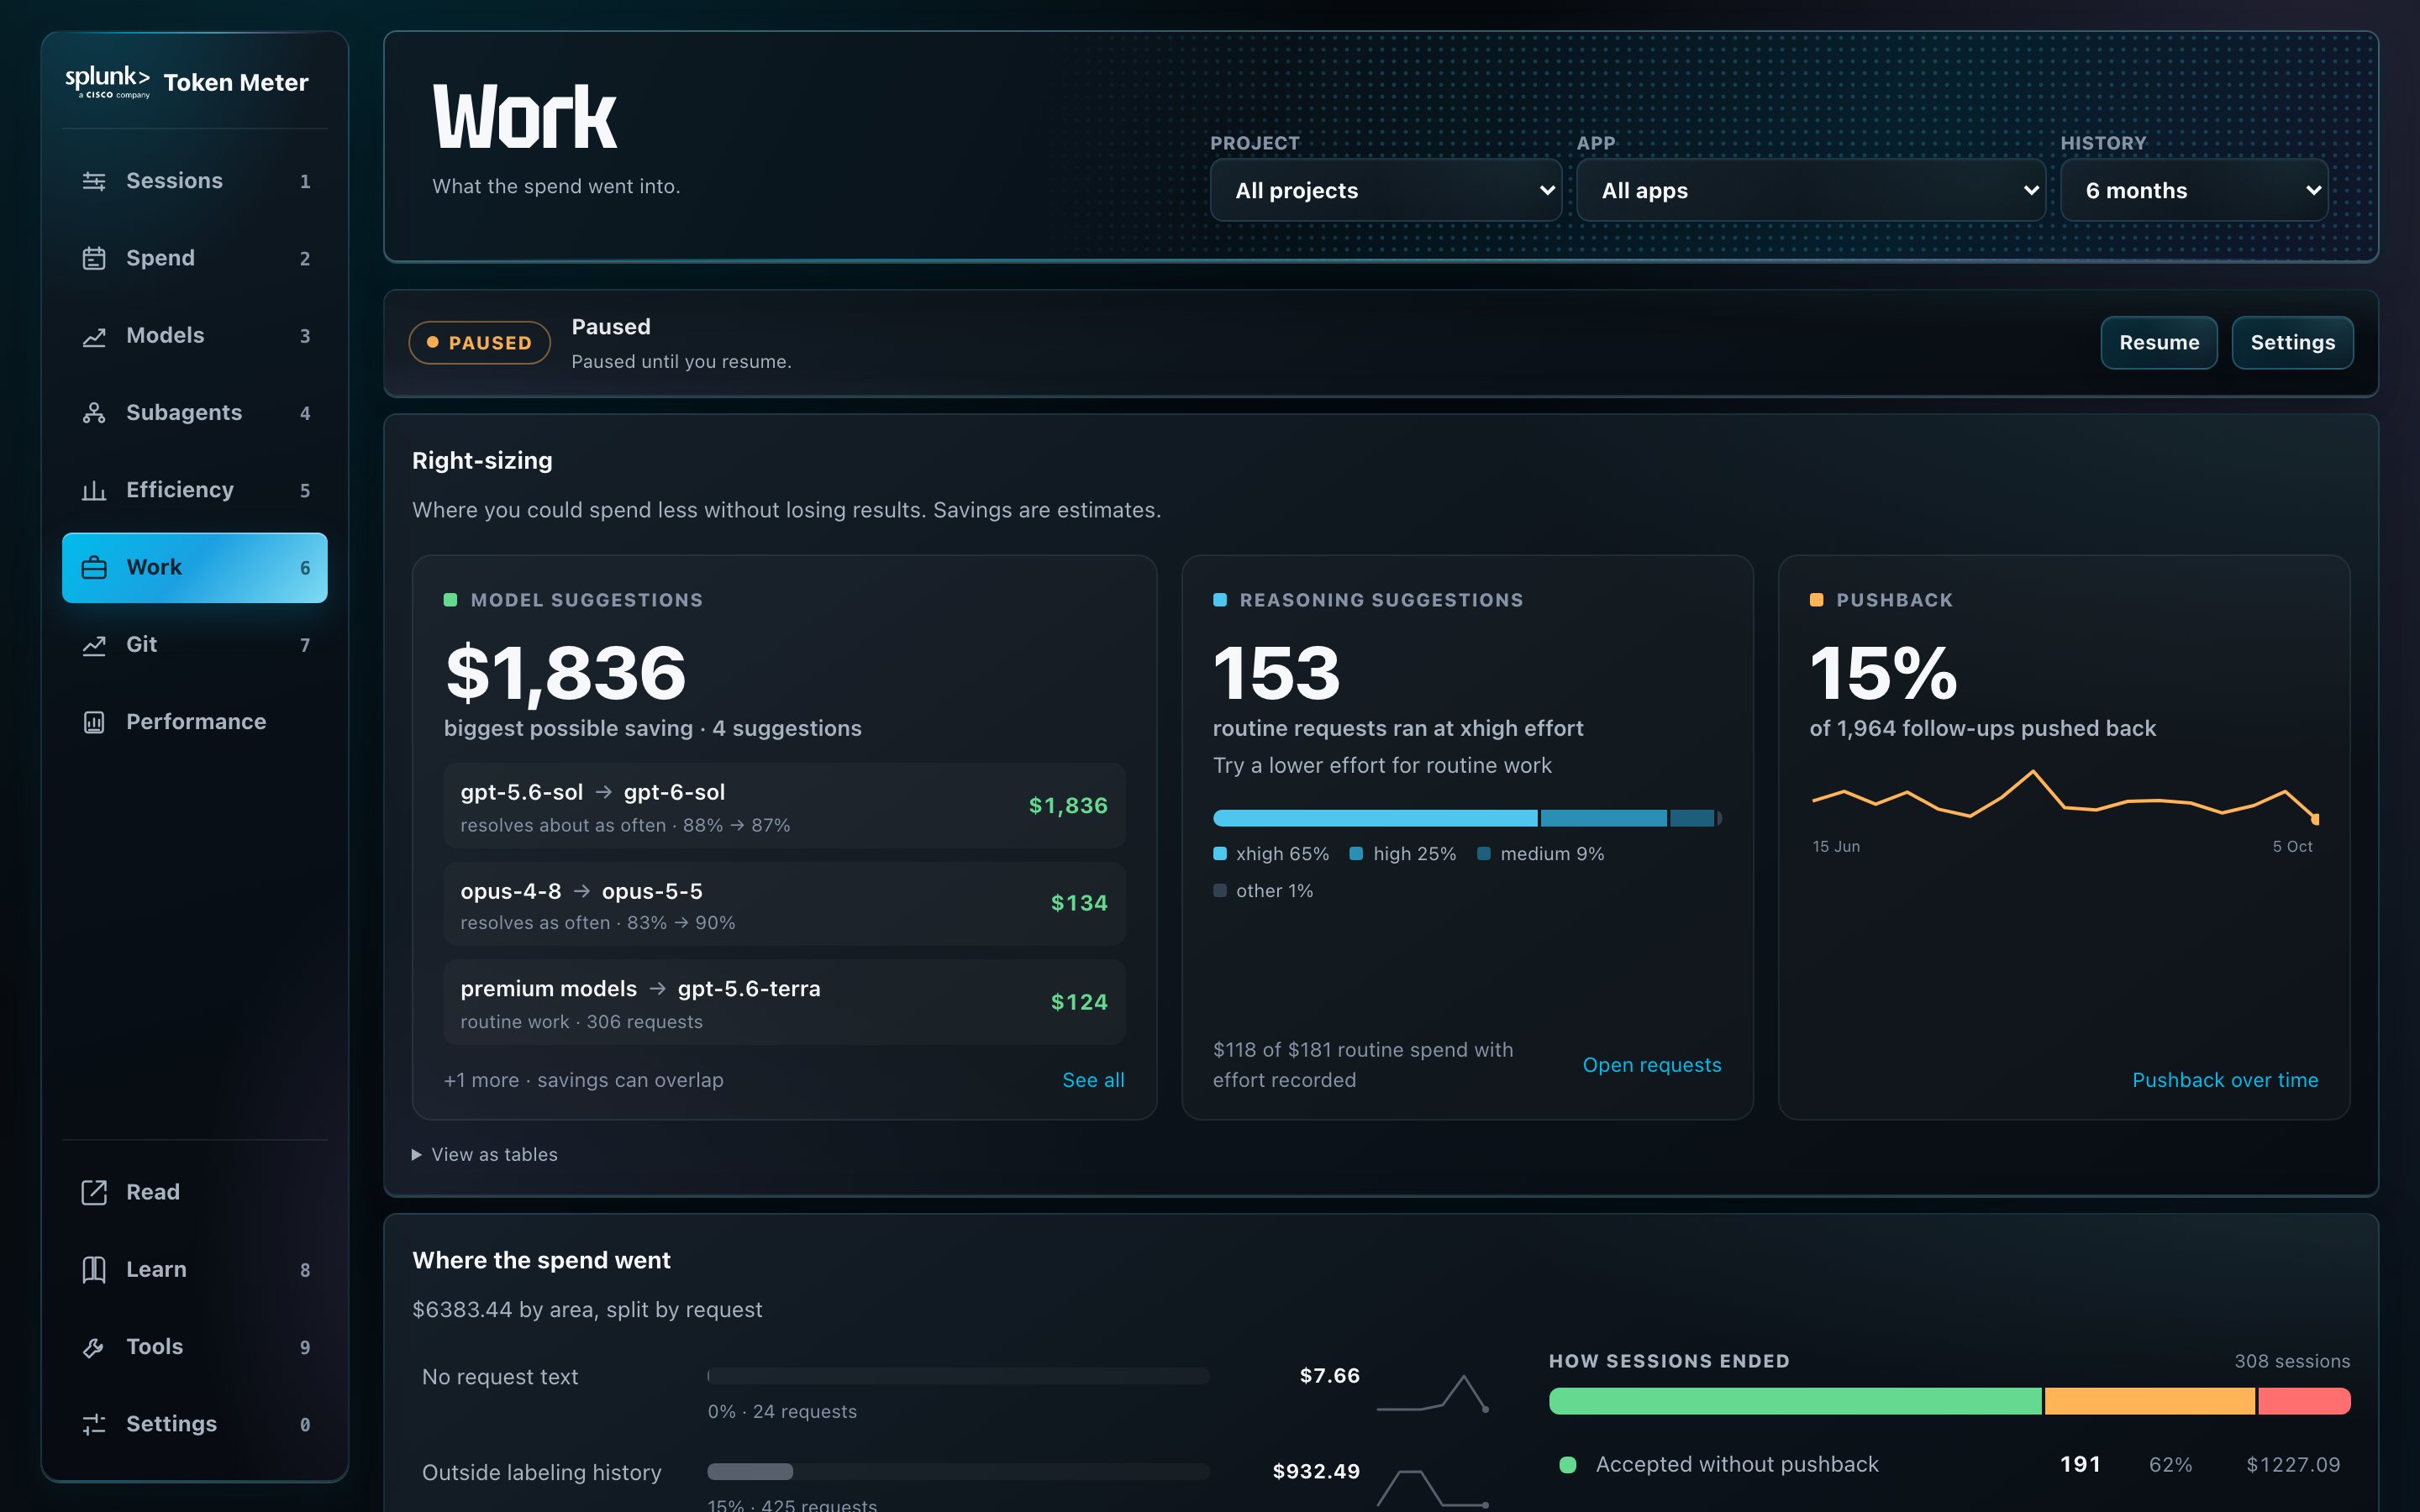
Each request is labeled on your Mac by Gemma in Ollama. Prompts never leave the machine.
Work page with model, reasoning, and pushback right-sizing cards
Biggest saving
$1,836
gpt-5.6-sol → gpt-6-sol, resolves about as often

Work page (⌥6, macOS) is coming soon. Savings are estimates. Only salted keys, labels, and counts are stored.

Can I do better? · 9 of 10 Coming soon Illustrative

Nudges while you work, not after

Sessions → Current sessions
Claude Code / claude-opus-5-5● Working
Cost
$4.20
Requests
34
Context
118K
!
Routine request on a premium modelMost of your Claude Code work runs on claude-sonnet-5
!
Long session30 or more requests so far. Consider a fresh start.
TM
Token Meternow
Two pushbacks in a rowClaude Code · claude-opus-5-5
Up to three per running session
  • Two pushbacks in a row
  • Complex work on a light model that's had pushback
  • Routine request on a premium model
  • High reasoning effort on routine work
  • Long session of 30+ requests

Gemma labels each request locally; suggestions refresh with the live session. Notifications name only the app and model.

Can I do better? · 10 of 10

Set goals on any metric

Output / $claude-opus-5-5
5.5Ktarget ≥ 10.7K
Improve 25% · this monthAt risk
Context loadClaude
290×target ≤ 178×
Lower 20% · this monthAt risk
Cost per 1K pushed linesAll agents
$26.73target ≤ $36
Cut 20% · custom rangeOn track
SpendAll agents
$2,040target ≤ $3,000
Custom · this month · projected $2,875On track
Seven metrics
SpendTokensOutput / $Context loadReasoning ratioFrontier shareCost per 1K lines
Scope
All agents, one agent, one model, or a set of models
Target
Improve or cut 10–25%, hold the current level, or type your own. This month or a custom range.
Pair a cost goal with a value goal, so cutting spend can't hide a drop in output per dollar.

My live goals from the Efficiency page. The menu bar lists them under Goals.

Part 3

The experimentation mindset

Treat AI usage as an experiment you can measure, not a bill you get surprised by.

Five levers · my evidence for each

Five levers to optimise the value

Model & reasoning

Match effort to task uncertainty and the cost of an error.

70→22%
of my spend at xhigh effort, Jul → Sep
Models

Task context

Load only what the task needs. Broad skills and unused tools add work.

83,907
unused tool tokens loaded into my prompts
Tools

Prompt caching

Keep stable context stable. Changes force a re-write.

55%
of my Opus bill was cache writes
Models · Efficiency

Outcome-focused prompts

Name the outcome, limit the scope, say how to test it.

15%
of my follow-ups were pushback
Work Soon

Avoid rework

One clear pass beats three corrections.

$33 vs $6
per session, recovered after pushback vs. accepted
Work Soon

Switching models mid-task? Start a fresh session with a short handoff instead of reloading the whole history.

The value loop

Change one thing. Then measure.

Things to change
Keep it only if it holds up on
Cost per successful resultQualityElapsed timeCorrection effort
Pick 2–3 repeatable tasks as your benchmark. Change one thing at a time, and share one finding with your team.

The value loop · compare the runs

"Which approach worked better?"

Same prompt · three models
5.1×
Opus cost vs. Haiku, same task
  1. 1
    Haiku · $0.079Fastest, 104K tokens
  2. 2
    Opus · $0.407The baseline
  3. 3
    InsightsToken Meter explains the gap: mostly cache writes
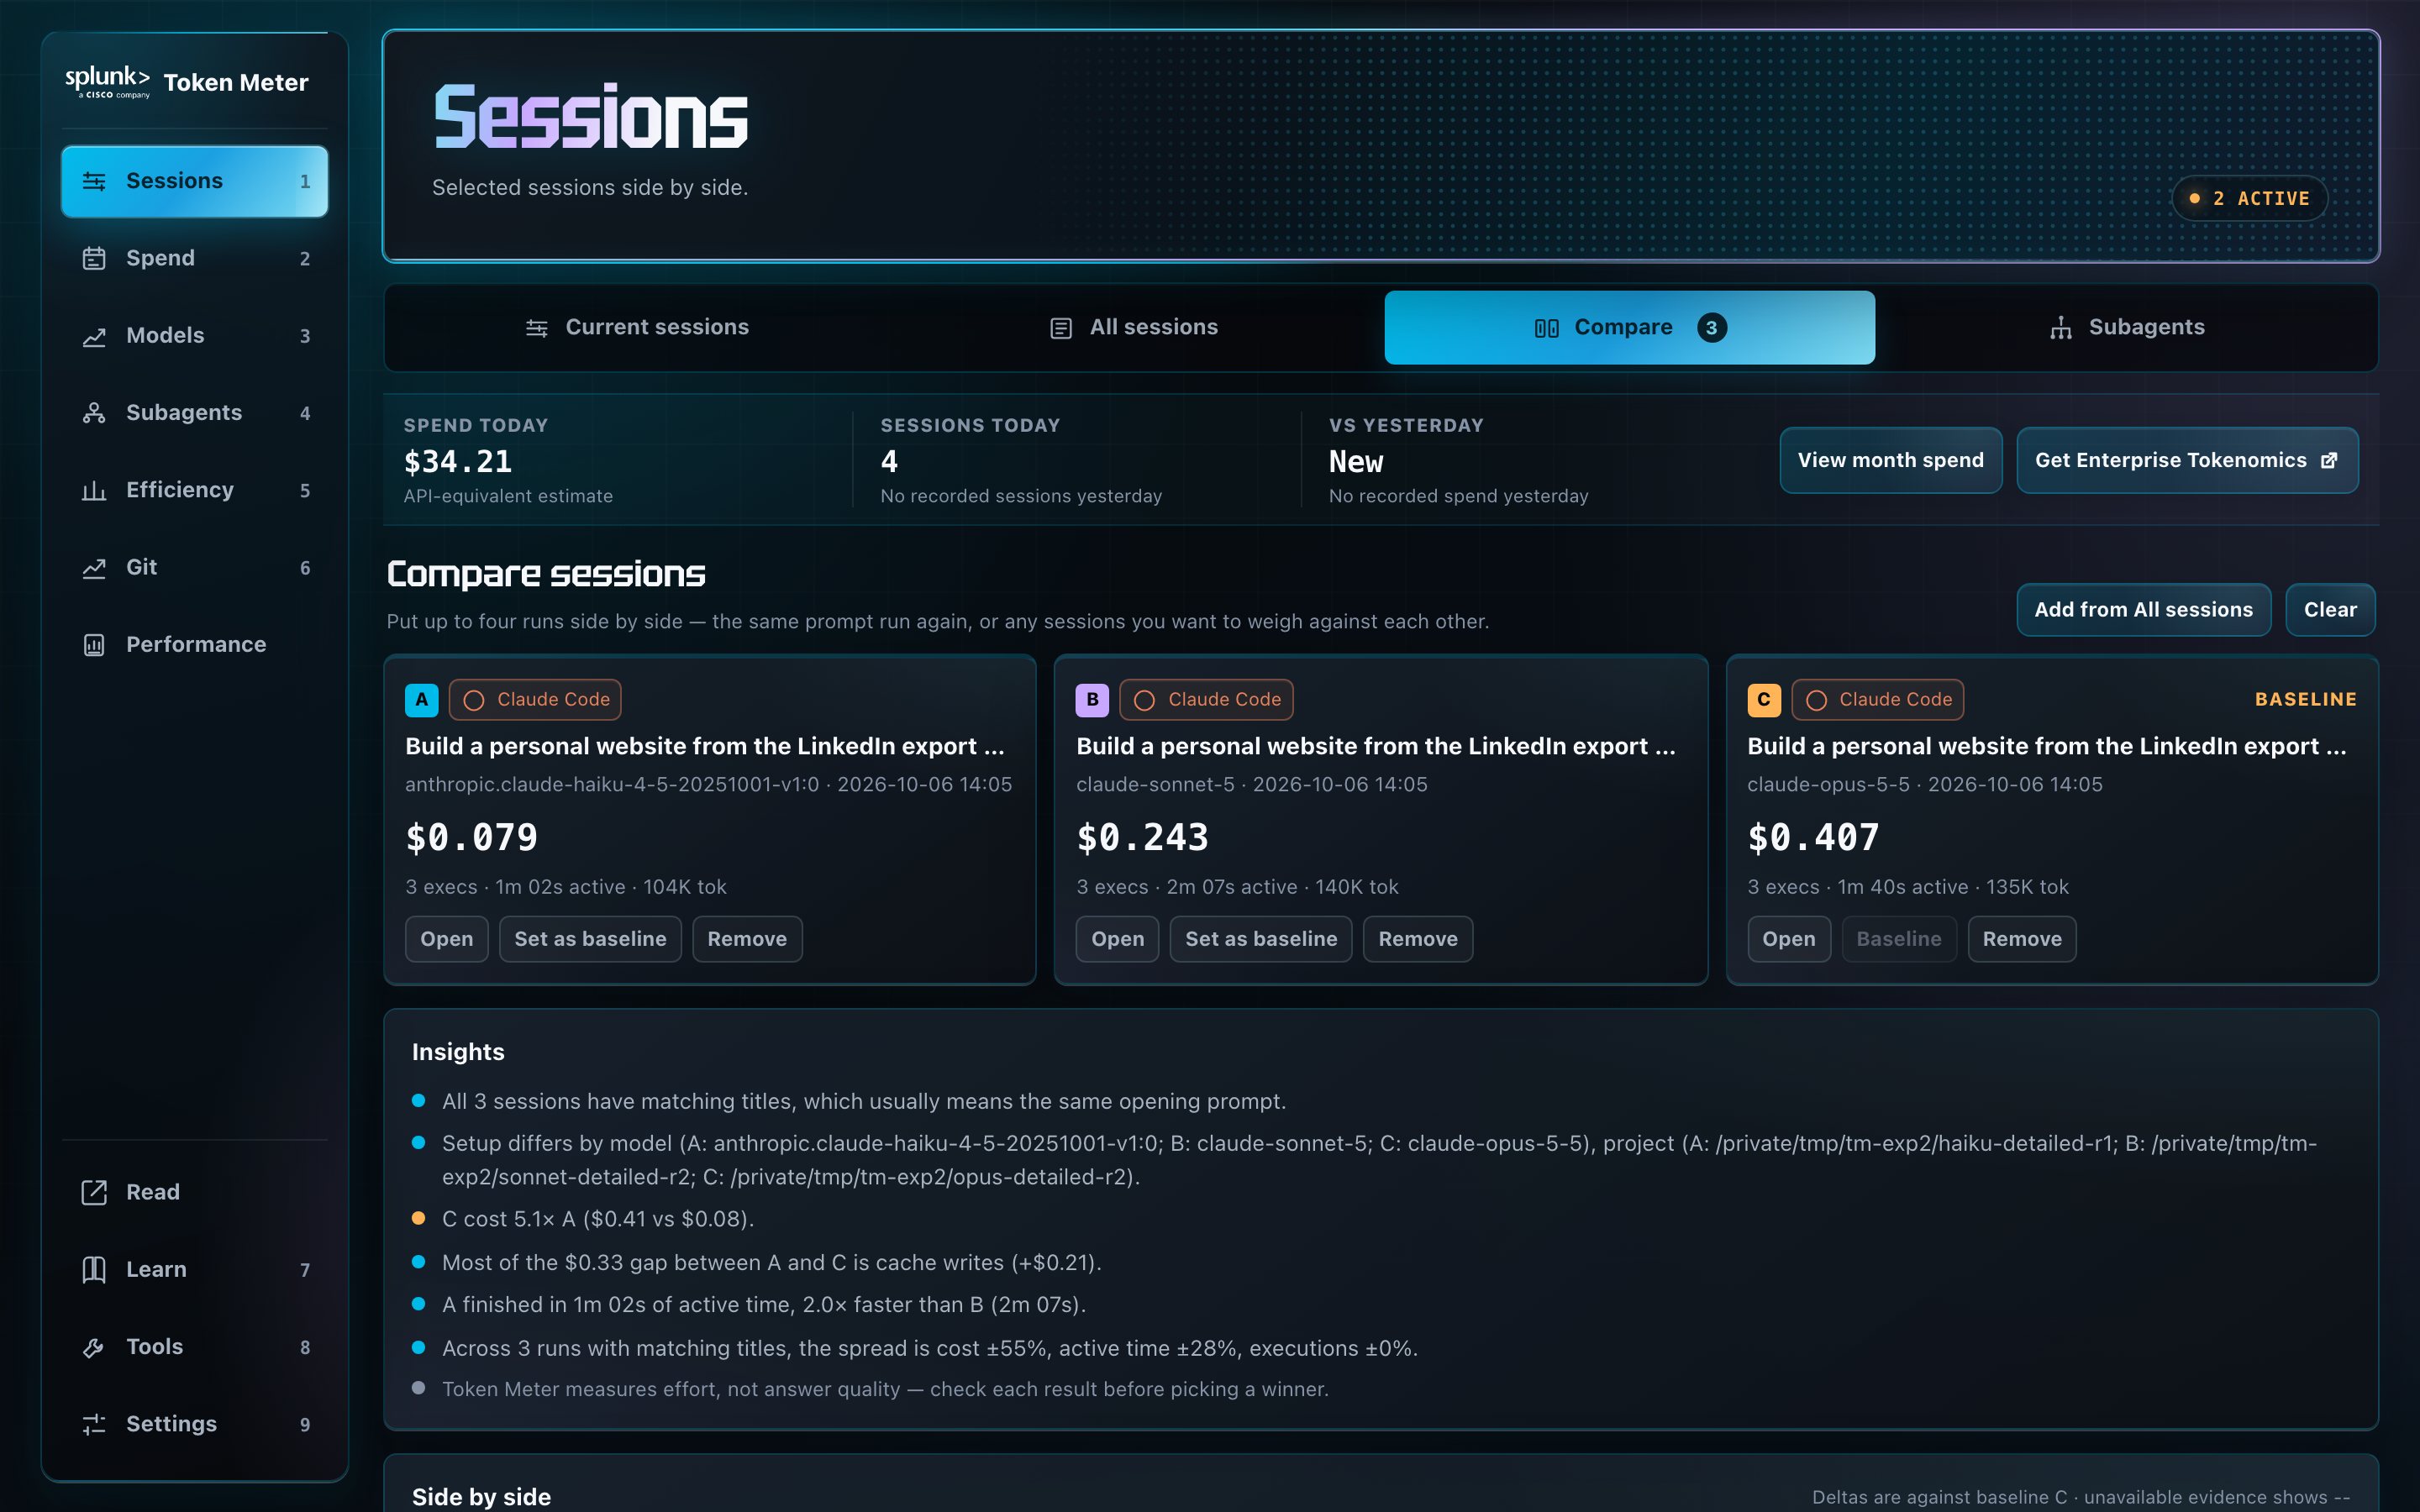
Cheapest isn't automatically best. Pick by task uncertainty, the cost of an error, and how you'll test the result. Then check quality before picking a winner.
Compare sessions view with three runs of one prompt on Haiku, Sonnet, and Opus
Where the gap came from
+$0.21
of the $0.33 gap between Haiku and Opus was cache writes

Ask your agent

Ask the Token Meter MCP

Claude Code · token-meter
My Oct 5 session cost $31. Why, and what should I have done differently?
⏺ Token Meter MCP · sessions() → trace(executions, context, events) → numbers only
What happened · 383 calls, $31.14
62%183 calls ran above 200K context and never compacted. Peak 491K.
3×$0.11 per call at 400K+, vs $0.035 under 100K
22%11 calls came 5+ min after the last one; the cache had expired: $6.86
What could have been better
1Compact or hand off near 200K ≈ $13 less, est.
2Pause under 5 min, or use the 1-hour cache up to $6.86
3Load the 6 skills it used, not 78
Token Meter MCP · local
8 read-only tools for Claude and Codex
check · usage · budget · capabilities · sessions · trace · stats · schema
Writes
Two session-budget setters, only with explicit confirmation
Returns
Numbers, never content

Turn it on in Settings → Agent connections. Real session from my laptop; savings are estimates at list price.

For teams

From your laptop to your team: Splunk Tokenomics

Token MeterTokenomics SourceLocal agent logsProvider spend APIs SeesSessions on this laptopAll spend, cloud sessions included CostList-price estimateSpend reported by the provider DetailEvery request, tool, cache, contextPer user, team, and org GoalsPersonal budgetsOrg budgets and alerts
Tokenomics shows the full bill, cloud sessions included. Token Meter shows why it happened. Use both.
Try Splunk Tokenomics → splunk.com/en_us/products/tokenomics.html

Part of Splunk Observability Cloud · 14-day free trial.

Get started

Five minutes to your first number

Terminal
$ git clone https://github.com/splunk/token-meter.git
$ ./token-meter/scripts/install
✓ server running
✓ menu bar running · starts at login
→ open http://127.0.0.1:8722
  1. 1
    Open Learn"First five minutes" onboarding
  2. 2
    Set a monthly budgetOn the Spend page
  3. 3
    Change one thing this weekThen compare the two runs

macOS and Linux. The Windows bootstrap is in beta. No sudo.

Make it yours

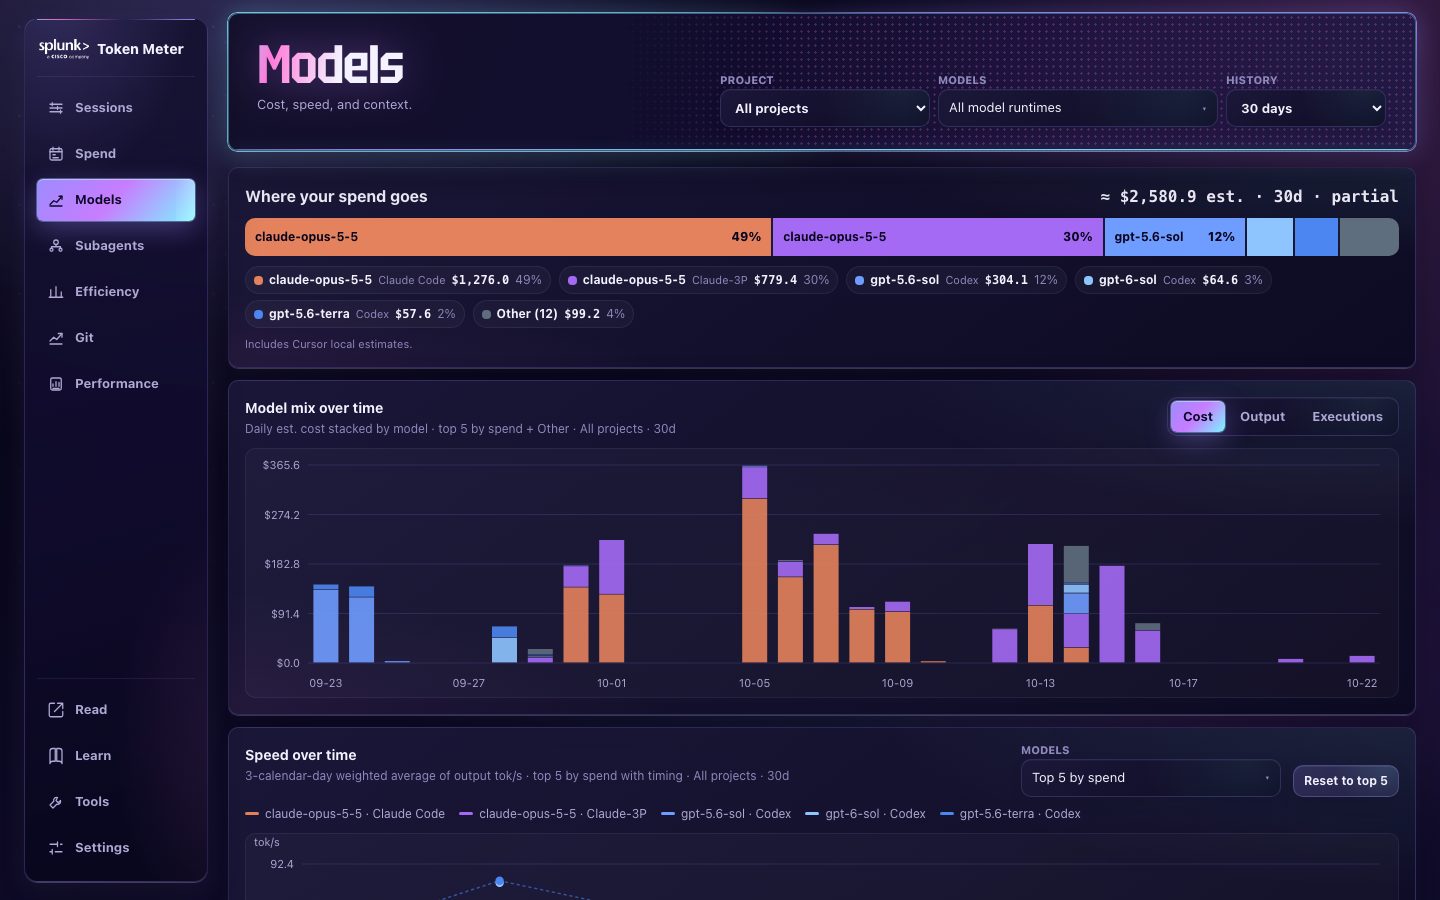
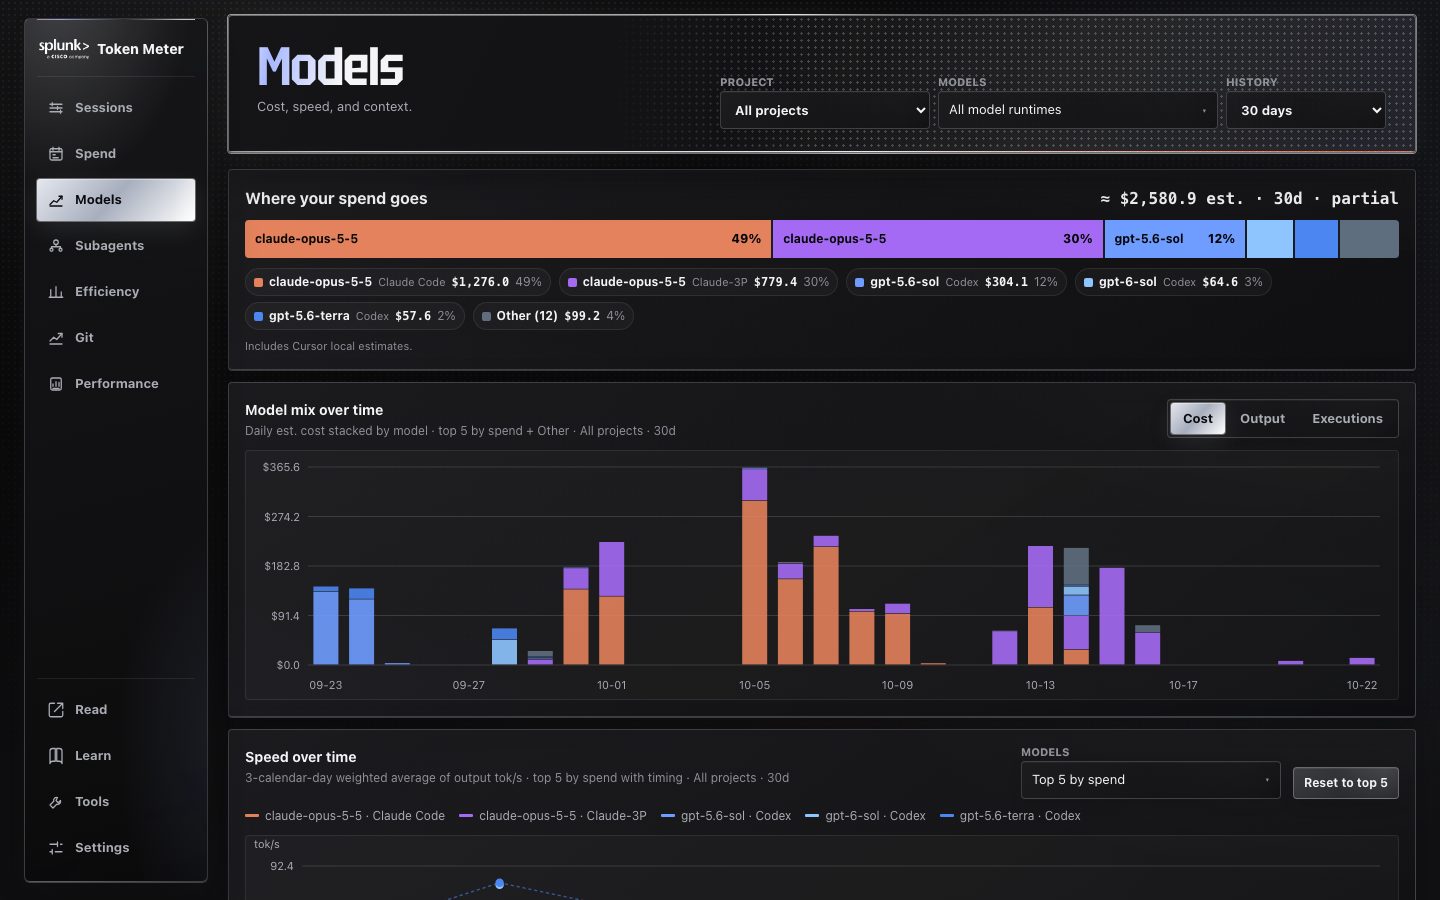
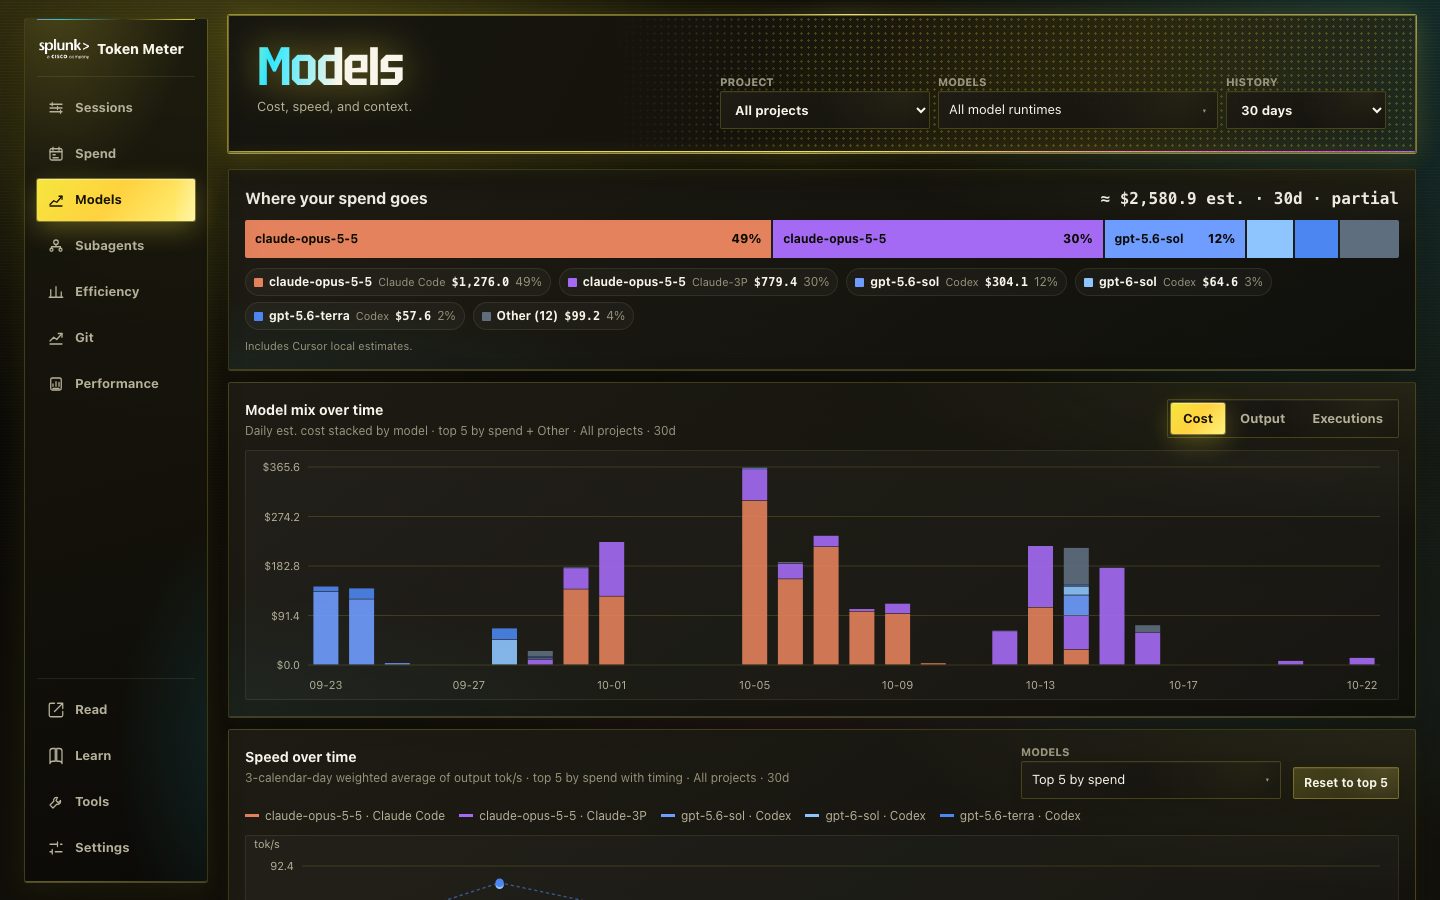
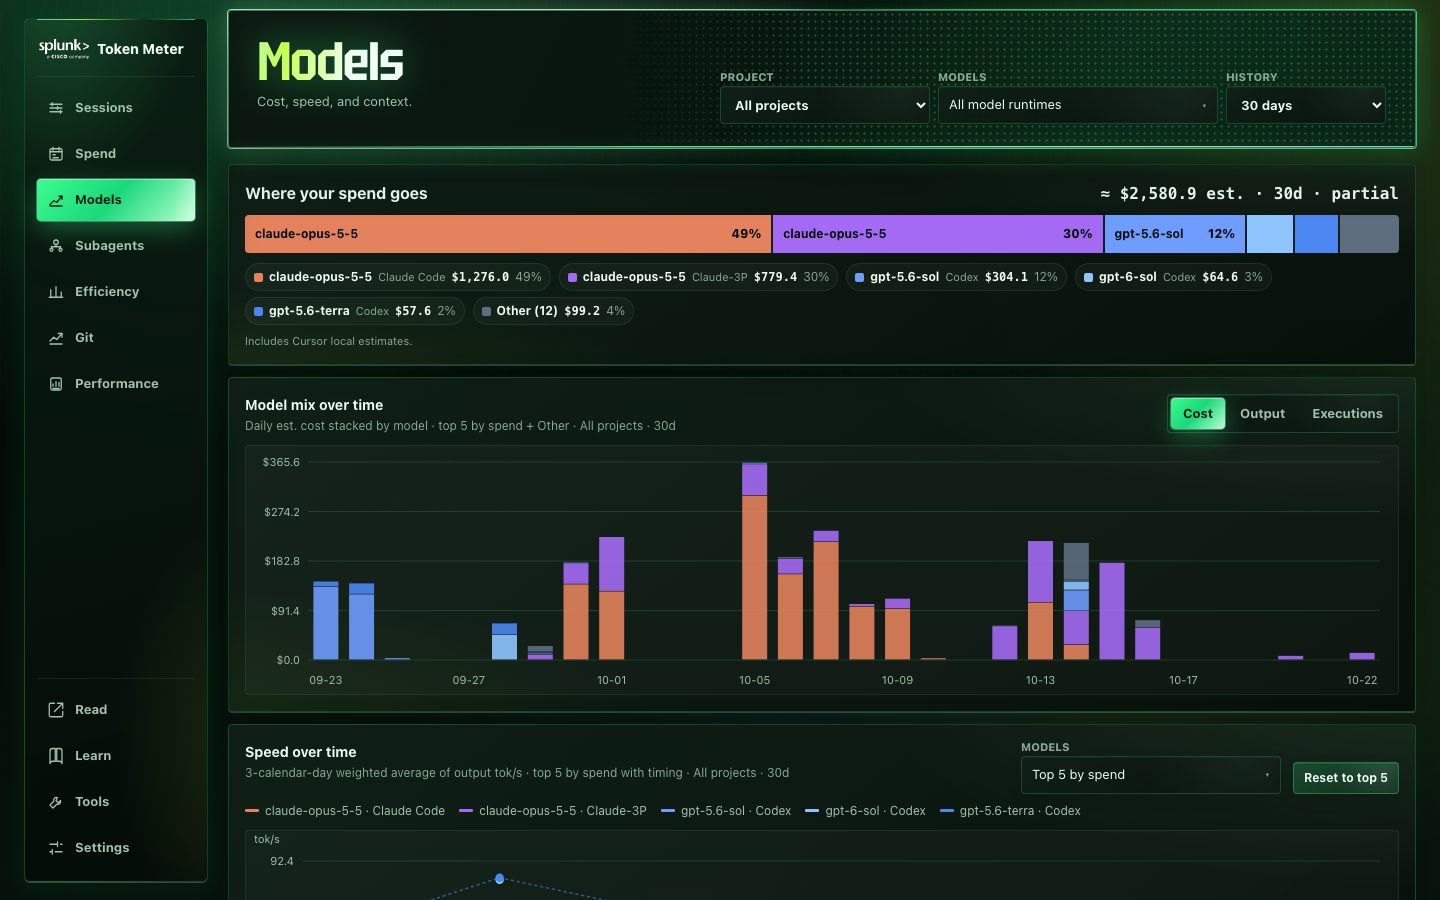
Eight themes, same numbers
Classic theme
ClassicThe original cyan instrument field
Nebula theme
NebulaUltraviolet glass, ion-cyan and mint
Monolith theme
MonolithGraphite and platinum, one vermilion tip
Voltage theme
VoltageVolt yellow on carbon
Phosphor theme
PhosphorTerminal green with falling-code rain
Omarchy theme
OmarchyDeep indigo with blue and violet neon
Ferrous theme
FerrousOxidized rust with molten amber
Afterglow theme
AfterglowPlum dusk, pink-to-amber sunset

Each browser keeps its own theme. Provider and status colors stay the same in every theme.

Before we go further

Can I trust the number?

TOKEN METER · ESTIMATE

✓Token countslocal logs
✓Public list pricechecked
✓Web search · $10 per 1Kif logged
✓5-min and 1-hour cache, fastif logged
✗Contract discountsnot visible
✗Gateway, Bedrock ratesnot visible
✗Seats, subscriptionsnot visible
–Unknown modelexcluded, not $0

AT LIST PRICE≈ $1,247
Full bill, cloud sessions included: Splunk Tokenomics

Reliable for comparing sessions, models, and trends on your own machine. Times use your local time zone.

Before we go further

Privacy is a feature

YOUR LAPTOP · 127.0.0.1 TRACES read-only Token Meter numbers anyone's cloud
Never leaves
Prompts, responses, reasoning, tool output, paths, token counts, costs
No
Cloud, analytics, telemetry, or third-party Python packages
Git page
Local push history only. Salted keys and line counts, never filenames or messages.

Thank you · Questions?

Spend tokens
like money.
Measure what
you get back.

Open source and built in the open. Every adapter, fix, and finding makes it better for the next engineer.

★ Star it⇄ Send a PR↗ Share with one teammate

macOS · Linux · Windows (beta)
Claude Code · Codex · Cursor · OpenCode · Kiro · Pi
Thank you, contributors
Know more about Token Meter
00:00Next: